ai_vector_core_utilization (AI Vector Core Instruction Proportion)
The AI Vector Core instruction proportion data does not contain the timeline information. The summary information is summarized in the ai_vector_core_utilization_*.csv file.
Applicable Products
Product |
Supported |
|---|---|
√ |
|
√ |
|
√ |
|
√ |
|
x |
|
x |
ai_vector_core_utilization_*.csv File
The file content is formatted as follows.
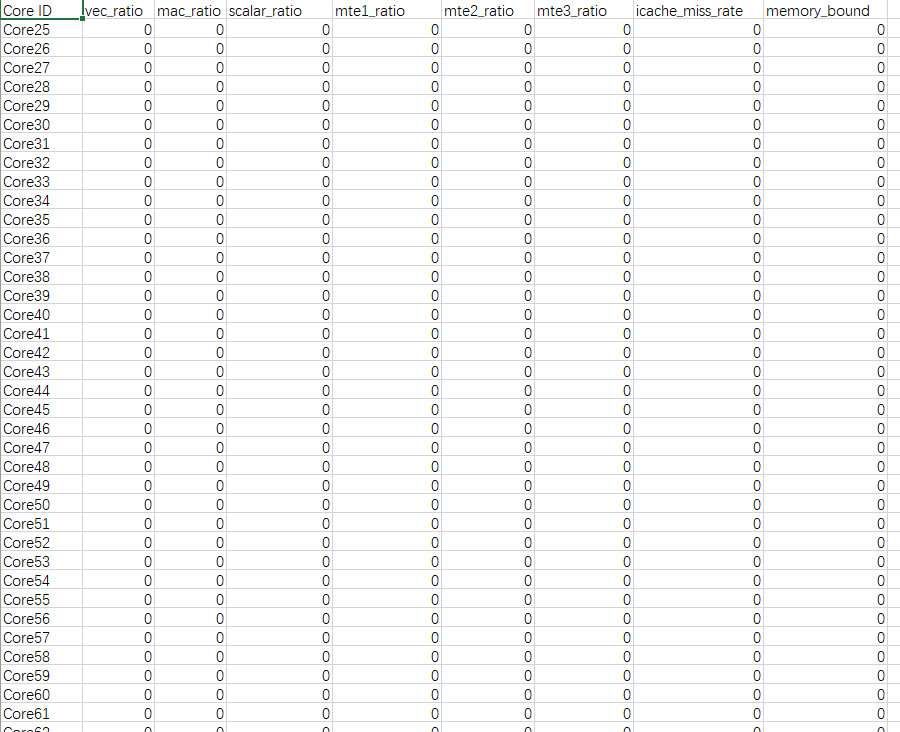
Field |
Description |
|---|---|
vec_ratio |
Ratio of cycles taken to execute Vector instructions to the total cycles. The |
mac_ratio |
Ratio of cycles taken to execute Cube instructions (fp16 and s16) to the total cycles. |
scalar_ratio |
Ratio of cycles taken to execute Scalar instructions to the total cycles. |
mte1_ratio |
Ratio of cycles taken to execute MTE1 instructions (L1-to-L0A/L0B transfer) to the total cycles. |
mte2_ratio |
Ratio of cycles taken to execute MTE2 instructions (DDR-to-AI Core transfer) to the total cycles. ( |
mte2_ratio |
Ratio of cycles taken to execute MTE2 instructions (on-chip memory to AI Core movement) to the total cycles. ( |
mte3_ratio |
Ratio of cycles taken to execute MTE3 instructions (AI Core-to-DDR transfer) to the total cycles. ( |
mte3_ratio |
Ratio of cycles taken to execute MTE3 instructions (AI Core to on-chip memory movement) to the total cycles. ( |
icache_miss_rate |
iCache miss rate, that is, L1 cache that does not hit instructions. The smaller the value, the better. |
memory_bound |
AI Core memory bound, calculated as: mte2_ratio/max(mac_ratio, vec_ratio). If the calculation result is less than 1, there is no memory bottleneck. If the result exceeds 1, a memory bottleneck exists. A larger value indicates a more severe memory bottleneck. |
See ai_core_utilization (AI Core Instruction Proportion) for more details. The AI Vector Core metric PipeUtilization in sample-based mode is taken as an example. |
|