ai_core_utilization (AI Core Instruction Proportion)
The timeline information of the AI Core instruction proportion data is displayed at the AI Core Utilization layer in the msprof_*.json file, and the summary information is summarized in the ai_core_utilization_*.csv file.
Applicable Products
AI Processor Type |
Supported |
|---|---|
√ |
|
√ |
|
√ |
|
√ |
|
√ |
|
√ |
|
√ |
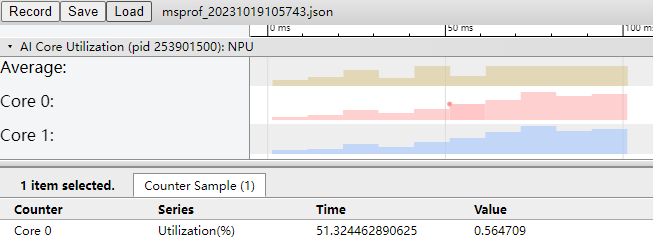
AI Core Instruction Proportion Data in msprof_*.json
The following shows the file content format.
Field |
Description |
|---|---|
Average |
Mean value. |
Core <ID> |
Core ID. |
utilization(%) |
Percentage of total execution cycles (counting from the first operator instruction executed by the AI Core to the completion of the last instruction executed) of a task on the AI Core in the current sampling period. |
ai_core_utilization_*.csv File
The file content is formatted as follows.
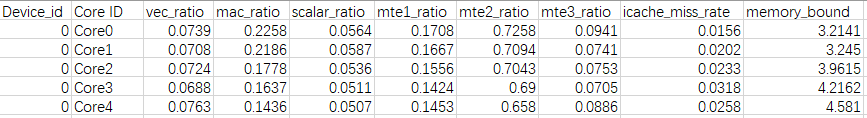
The file display result varies according to the value of --aic-metrics. The table describes the fields.
- Supported fields may vary by product. Please refer to the actual result files for the final list of fields.
- The following fields are generated when --task-time is set to l1 and --aic-mode is set to sample-based. If --task-time is set to l0, this field is not profiled and N/A is displayed. The generated data is controlled by the aic_metrics parameter.
Field |
Description |
|---|---|
vec_ratio |
Ratio of cycles taken to execute Vector instructions to the total cycles. For the |
mac_ratio |
Ratio of cycles taken to execute Cube instructions to the total cycles. |
scalar_ratio |
Ratio of cycles taken to execute Scalar instructions to the total cycles. |
mte1_ratio |
Ratio of cycles taken to execute MTE1 instructions (L1-to-L0A/L0B transfer) to the total cycles. |
mte2_ratio |
Ratio of cycles taken to execute MTE2 instructions (DDR-to-AI Core transfert) to the total cycles. |
mte3_ratio |
Ratio of cycles taken to execute MTE3 instructions (AI Core-to-DDR transfer) to the total cycles. The |
icache_miss_rate |
iCache is the L2 cache reserved for instructions. If the value of icache_miss_rate is high, the AI Core reads instructions at a low efficiency. |
fixpipe_ratio |
Ratio of cycles taken to execute fixpipe instructions (L0C-to-OUT/L1 transfer) to the total cycles. |
memory_bound |
AI Core memory bound, calculated as: mte2_ratio/max(mac_ratio, vec_ratio). If the calculation result is less than 1, there is no memory bottleneck. If the result exceeds 1, the AI Core spends most of its time on memory data movement rather than computation during task execution. A larger value indicates a more severe memory bottleneck. The |
Field |
Description |
|---|---|
mac_fp16_ratio |
Ratio of cycles taken to execute Cube fp16 instructions to the total cycles. |
mac_int8_ratio |
Ratio of cycles taken to execute Cube int8 instructions to the total cycles. |
vec_fp32_ratio |
Ratio of cycles taken to execute vec fp32 instructions to the total cycles. For the |
vec_fp16_ratio |
Ratio of cycles taken to execute vec fp16 instructions to the total cycles. For the |
vec_int32_ratio |
Ratio of cycles taken to execute vec int32 instructions to the total cycles. For the |
vec_misc_ratio |
Ratio of cycles taken to execute vec misc instructions to the total cycles. For the |
cube_fops |
Floating-point operations (FLOPs, that is, fops in this field) of the Cube type, indicating the computation amount. This field can be used to measure the complexity of an algorithm or model. |
vector_fops |
Floating-point operations (FLOPs, that is, fops in this field) of the Vector type, indicating the computation amount. This field can be used to measure the complexity of an algorithm or model. The |
Field |
Description |
|---|---|
ub_read_bw(GB/s) |
UB read bandwidth, in GB/s. For the |
ub_write_bw(GB/s) |
UB write bandwidth, in GB/s. For the |
l1_read_bw(GB/s) |
L1 read bandwidth, in GB/s. |
l1_write_bw(GB/s) |
L1 write bandwidth, in GB/s. |
l2_read_bw |
L2 read bandwidth, in GB/s. The |
l2_write_bw |
L2 write bandwidth, in GB/s. For the |
main_mem_read_bw(GB/s) |
Main memory read bandwidth, in GB/s. |
main_mem_write_bw(GB/s) |
Main memory write bandwidth, in GB/s. For the |
Field |
Description |
|---|---|
l0a_read_bw(GB/s) |
l0a read bandwidth, in GB/s. |
l0a_write_bw(GB/s) |
l0a write bandwidth, in GB/s. |
l0b_read_bw(GB/s) |
l0b read bandwidth, in GB/s. |
l0b_write_bw(GB/s) |
l0b write bandwidth, in GB/s. |
l0c_read_bw(GB/s) |
Bandwidth rate for Vector to read data from L0C, in GB/s. |
l0c_write_bw(GB/s) |
Bandwidth rate for Vector to write data to L0C, in GB/s. This field is not supported by the |
l0c_read_bw_cube(GB/s) |
Bandwidth rate for Cube to read data from L0C, in GB/s. |
l0c_write_bw_cube(GB/s) |
Bandwidth rate for Cube to write data to L0C, in GB/s. |
Note: Data about the MemoryL0 metric of the AI Vector Core is 0. |
|
Field |
Description |
|---|---|
ub_read_bw_vector(GB/s) |
Bandwidth rate for Vector to read data from UB, in GB/s. |
ub_write_bw_vector(GB/s) |
Bandwidth rate for Vector to write data to UB, in GB/s. |
ub_read_bw_scalar(GB/s) |
Bandwidth rate for Scalar to read data from UB, in GB/s. |
ub_write_bw_scalar(GB/s) |
Bandwidth rate for Scalar to write data to UB, in GB/s. |
ub_fixp2ub_write_bw(GB/s) |
Write bandwidth of Vector fixpipe to UB (excluding the UB backpressure), in GB/s. Only the |
Field |
Description |
|---|---|
vec_bankgroup_cflt_ratio |
Ratio of cycles taken to execute vec_bankgroup_stall_cycles instructions to the total cycles. Improper block stride settings in Vector instructions can lead to bank group conflicts. This field is not supported by the |
vec_bank_cflt_ratio |
Ratio of cycles taken to execute vec_bank_stall_cycles instructions to the total cycles. Improper read/write pointer addresses for Vector instruction operands can lead to bank conflicts. This field is not supported by the |
vec_resc_cflt_ratio |
Ratio of cycles taken to execute vec_resc_cflt_ratio instructions to the total cycles. If an operator involves multiple compute units, ensure that they are concurrently scheduled. When a compute unit is working, but the operator logic still delivers instructions to it, the overall computing power is not fully utilized. This field is not supported by the |
Field |
Description |
|---|---|
write_cache_hit |
Write cache hits. The |
write_cache_miss_allocate |
Cache re-allocations upon write cache missing. The |
r*_read_cache_hit |
Read cache hits in the r* channel. The |
r*_read_cache_miss_allocate |
Cache re-allocations upon read cache missing in the r* channel. The |
read_local_l2_hit |
Read cache hits. Only the |
read_local_l2_miss |
Read cache misses. Only the |
read_local_l2_victim |
Number of read cache misses that trigger cache victimization. Only the |
write_local_l2_hit |
Write cache hits. Only the |
write_local_l2_miss |
Write cache misses. Only the |
write_local_l2_victim |
Number of write cache misses that trigger cache victimization. Only the |
Availability: |
|
Field |
Description |
|---|---|
read_main_memory_datas(KB) |
Amount of data read from the on-chip memory, in KB. |
write_main_memory_datas(KB) |
Amount of data written to the on-chip memory, in KB. |
gm_to_l1_datas(KB) |
Amount of data transferred from GM to L1, in KB. |
l0c_to_l1_datas(KB) |
Amount of data transferred from L0C to L1, in KB. |
l0c_to_gm_datas(KB) |
Amount of data transferred from L0C to GM, in KB. |
gm_to_ub_datas(KB) |
Amount of data transferred from GM to UB, in KB. |
ub_to_gm_datas(KB) |
Amount of data transferred from UB to GM, in KB. |
Availability: |
|