Quantization Introduction
Quantization is widely used in deep learning models, especially during inference. Through quantization, models can run more efficiently on hardware, reducing computational resource consumption and accelerating the inference process while lowering model storage requirements.
CANN operator quantization refers to the computational process of converting input tensors of matrix (cube) operators such as Matmul in neural networks from high-bit to low-bit representations, while simultaneously generating the corresponding quantization parameter scale. After low-bit cube computation is completed, the low-bit values can be converted back to high-bit values using the quantization parameter scale, thereby ensuring the correctness of the overall computation result (with an effect approximately equivalent to direct high-bit computation) and effectively improving computational efficiency.
- Static quantization: Uses predetermined quantization parameters for quantization. In inference scenarios, quantization of weights generally adopts static quantization, which yields better quantization operator performance.
- Dynamic quantization: Uses input data to compute quantization parameters online for quantization. In inference scenarios, quantization of activations generally adopts dynamic quantization, which better adapts to data variations and offers higher precision. In training scenarios, dynamic quantization is also generally adopted to improve quantization precision. Note that dynamic quantization, due to online generation of quantization parameters, results in slightly degraded quantization operator performance.
Quantization Modes
A quantization mode (also referred to as quantization granularity) defines the level of quantization computation applied to different input tensors of an operator. Common quantization modes include:
NOTE
- The variables m, n, and k represent the sizes of different axes of a tensor.
- The left matrix and right matrix refer to the two input tensors used for matrix multiplication in cube operators. Generally, the left matrix represents the activation and the right matrix represents the weight. Users should interpret and apply these concepts based on their actual scenarios.
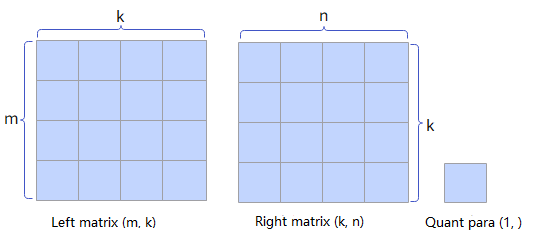
Per-tensor quantization (abbreviated as T quantization): The quantization object can be either the left matrix or the right matrix. All elements of a tensor share a single quantization parameter.
Assume the left matrix has a shape of (m, k) and the right matrix has a shape of (k, n), where k is the reduce axis. The shape of the generated quantization parameter is (1, ).
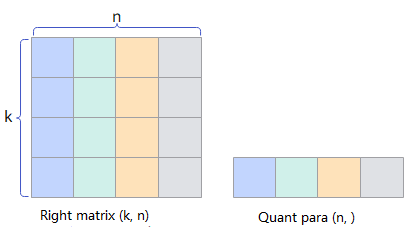
Per-channel quantization (abbreviated as C quantization): The quantization object is the right matrix, and each channel uses an independent quantization parameter.
Assume the right matrix has a shape of (k, n), where k is the reduce axis, and the generated quantization parameter has a shape of (n, ).
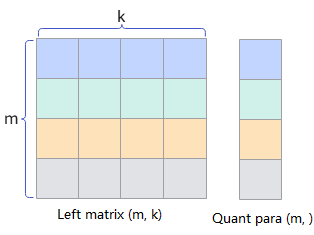
Per-token quantization (abbreviated as K quantization): The quantization object is the left matrix, and each token uses an independent quantization parameter.
Assume the left matrix has a shape of (m, k), where k is the reduce axis, and the shape of the generated quantization parameter is (m, ).
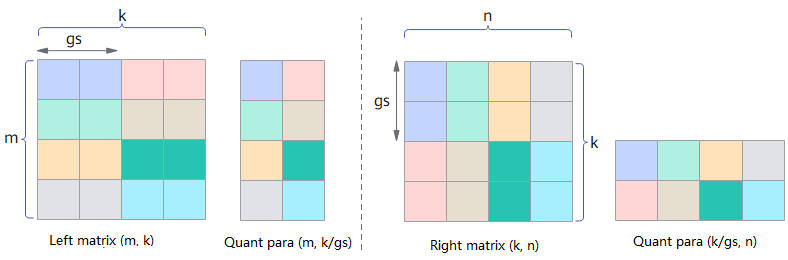
Per-group quantization (abbreviated as G quantization): The quantization object can be either the left matrix or the right matrix. Data is grouped along the reduce axis, and each group uses an independent quantization parameter.
- Assume the left matrix has a shape of (m, k), where k is the reduce axis. Data is grouped along the k axis with a group size of gs, and the shape of the generated quantization parameter is (m, k/gs).
- Assume the right matrix has a shape of (k, n), where k is the reduce axis. Data is grouped along the k axis with a group size of gs, and the shape of the generated quantization parameter is (k/gs, n).
Per-block quantization (abbreviated as B quantization): The quantization object can be either the left matrix or the right matrix. Data is partitioned into blocks along all axes, with each block using independent quantization parameters.
- Assuming the left matrix has a shape of (m, k), where k is the reduce axis, data is grouped by (bs, bs) blocks along the m and k axes respectively, where bs is the block size. The resulting quantization parameters have a shape of (m/bs, k/bs).
- Assuming the right matrix has a shape of (k, n), where k is the reduce axis, data is grouped by (bs, bs) blocks along the k and n axes respectively, where bs is the block size. The resulting quantization parameters have a shape of (k/bs, n/bs).
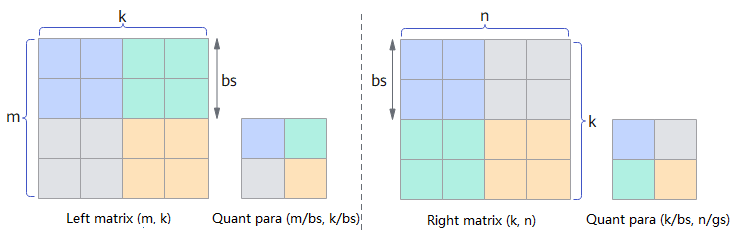
Common Combined Quantization
- Full quantization: generally refers to the mode in which both the left and right matrices are quantized, including
- pertensor-perchannel quantization mode (abbreviated as T-C quantization mode)
- pertoken-perchannel quantization mode (abbreviated as K-C quantization mode)
- pergroup-perblock quantization mode (abbreviated as G-B quantization mode)
- pertensor-perchannel-pergroup quantization mode (T-CG quantization mode for short)
- perblock-perblock quantization mode (B-B quantization mode for short)
- Pseudo quantization: generally refers to the mode of quantizing the weight matrix, including the perchannel quantization mode (C quantization mode for short).
- mx quantization: essentially Microscaling quantization, which maintains model accuracy at extremely low bit-widths (e.g., 1 bit) by dynamically adjusting scaling factors. Here it refers to the pergroup-pergroup quantization mode (G-G quantization mode for short), which is a special case where the quantization parameter type is FLOAT8_E8M0 and the group size is 32.