GroupedMatmulTransFusionPass

Description

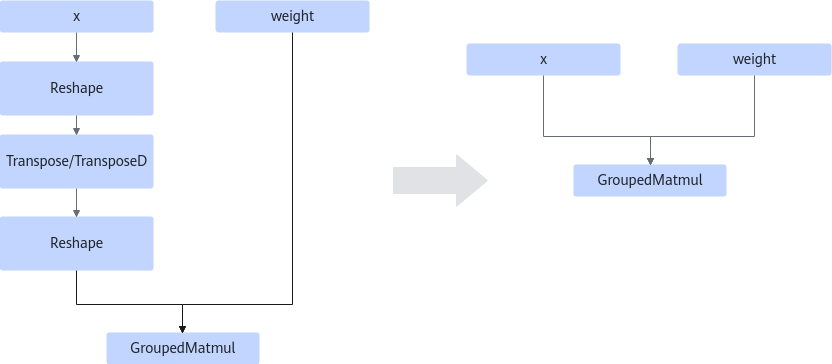
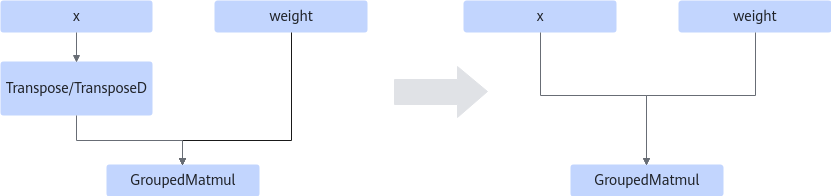
Pattern 1: Deletes Transpose or TransposeD from the graph and encodes the x/weight transformation information to operator attributes. See the following figure.

This fusion pattern supports the following products:
Atlas 200I/500 A2 inference products

Atlas inference products

Atlas training products

Atlas A2 training products / Atlas A2 inference products

Atlas A3 training products / Atlas A3 inference products

Ascend 950PR / Ascend 950DT

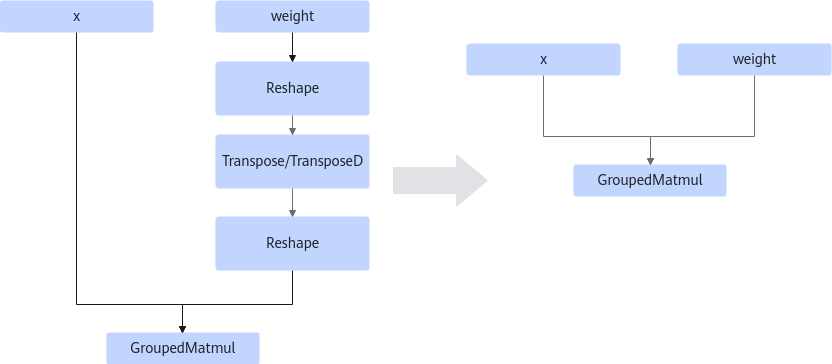
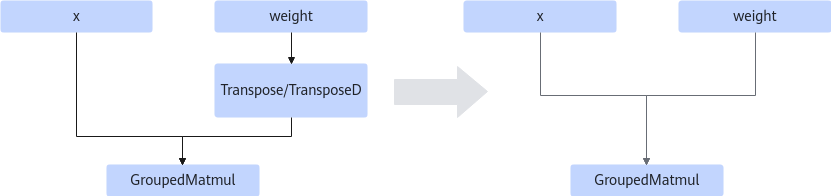
Pattern 2: Deletes Reshape, Transpose/TransposeD, and Reshape connected to the x/weight from the graph and encodes the weight transformation information to operator attributes. See the following figure.

This fusion pattern supports the following products:
Atlas A2 training products / Atlas A2 inference products

Atlas A3 training products / Atlas A3 inference products

Ascend 950PR / Ascend 950DT

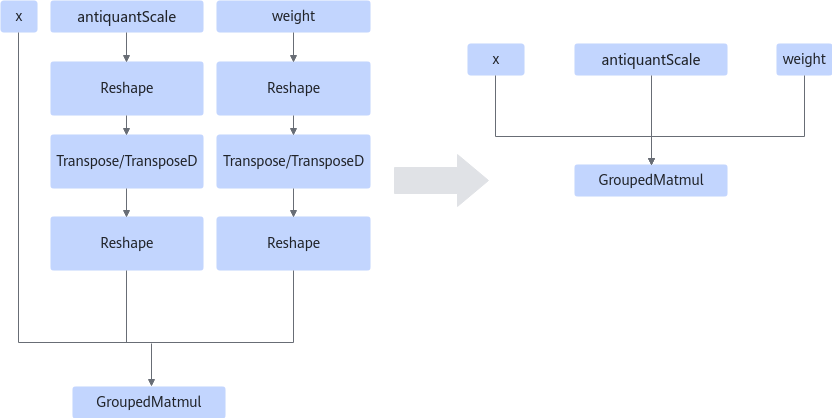
Pattern 3: For Ascend 950PR / Ascend 950DT in fake-quantization use cases, deletes Reshape+Transpose/TransposeD+Reshape connected to weight and antiquantScale from the graph and encodes the weight transformation information to operator attributes. See the following figure.

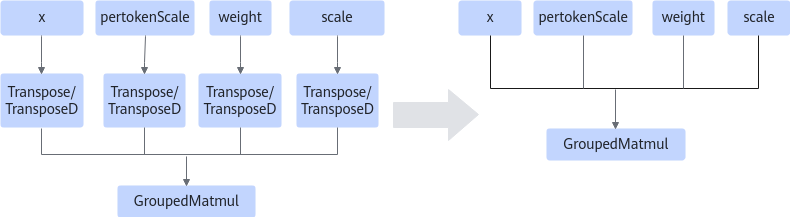
Pattern 4: For Ascend 950PR / Ascend 950DT in MX/GB quantization use cases, deletes Transpose or TransposeD from the graph and encodes the x and weight transformation information to operator attributes. See the following figure.

For Ascend 950PR / Ascend 950DT in MX/GB quantization use cases, scale follows the weight transformation information, and pertokenScale follows the x transformation information.

Constraints

  • Only the scenario where x, weight, and y are single tensors is supported (single tensor indicates that there is only one tensor in the tensorList input).
  • Transpose/TransposeD supports transpose on the second and third axes.