PromptFlashAttentionQuantFusionPass
Description
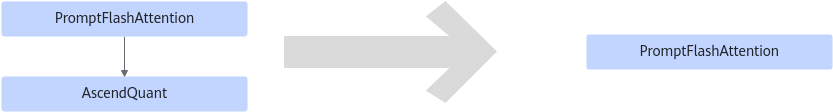
Fuses PromptFlashAttention+AscendQuant into the PromptFlashAttention operator in the quantization scenario. The scale and offset parameters of quant are converted into the input parameters quant_scale2 and quant_offset2 of pfa.
Constraints
- PromptFlashAttention supports only fp16 output.
- AscendQuant supports only fp16 input and int8 output.
- quant_scale2 and quant_offset2 of the PromptFlashAttention operator must be empty.
- The PromptFlashAttention operator can have only one output.
Applicable Products
Parent topic: Graph Fusion Patterns