Approximate Computing with EXP
Description
EXP uses m8v2 approximate computing to improve performance.
During attention computation, EXP takes a long time for a single operator. Therefore, you can use fast EXP.
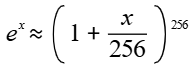
Built on this theory, the EXP M8V2 solution improves precision while maintaining performance:
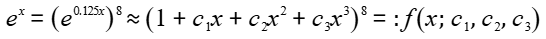
The polynomial can use the Qin Jiushao algorithm to reduce the number of operations:
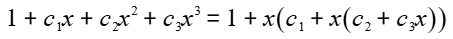
The coefficients are determined after numerical optimization.
How to Enable
Set kernelType to KERNELTYPE_EXP_M8V2.
- Operator input list
Parameter
Dimension
Data Type
Format
cpu/npu
Description
Q
[ntokens, heads, headSize]
float16
ND
npu
nTokens: sum(qSeqlen), and the sum is rounded up to the nearest multiple of 16.
K
[ntokens, kvHead, headSize]
float16
ND
npu
-
V
[ntokens, kvHead, headSize]
float16
ND
npu
The v shape is the same as that of k.
Attention_mask
Compressed mask: maxSeqlen = 128[1, 128/16, 128, 16]
float16
NZ
npu
This parameter is not passed when maskType is MASK_TYPE_UNDEFINED (0).
seqlen
[batch]
int32/uint32
ND
npu
-
- Operator output list
Parameter
Dimension
Data Type
Format
cpu/npu
Description
output
[nTokens, head_num, head_size]
float16
ND
npu
Output.
Constraints
- headSize must be equal to headSizeV. MLA is not supported.
- headSize must be 16-aligned.
- M8V2 is supported only for
Atlas inference products . - The mask type can only be MASK_TYPE_UNDEFINED or MASK_TYPE_NORM.
- calcType can only be PA_ENCODER.
- headNum can differ from kvHeadNum.
- qkScale normalization is supported.
- qScale scaling is not supported.
- quantType, outDataType, batchRunStatusEnable, isTriuMask, clampType, clampMin, clampMax, kvcacheCfg, scaleType, mlaVHeadSize, cacheType and windowSize support only the default values.