Formula
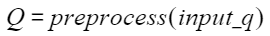
preprocess contains the scaling of q. The scaling coefficient is specified by qScale. When clamp scaling is enabled, torch.clamp is performed on q.
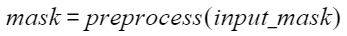
When mask compression is enabled, preprocess compresses the mask.
- When calcType is not PA_ENCODER and kvCacheCfg is not K_BYPASS_V_BYPASS:
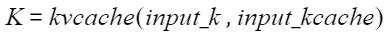
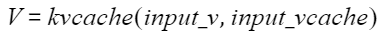
This step updates k and v to kvCache. For details, see KVCacheOperation.
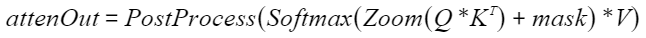
The Zoom function contains scaling of the
 result. The scaling coefficient is specified by qkScale, which is generally 1/sqrt(head_size). When logN scaling is enabled, the scaling coefficient is specified by the input tensor logN. The PostProcess function reshapes the result.
Parent topic: SelfAttentionOperation