Matmul Dequantization and Bias Addition
Applicable Products
Hardware Model |
Supported |
Remarks |
|---|---|---|
Atlas 350 accelerator cards |
√ |
- |
√ |
- |
|
√ |
- |
|
√ |
|
|
√ |
|
|
√ |
The input and output tensors of the bf16 data type are not supported. |
Description
Performs Matmul and dequantization. The hasBias parameter is used to control whether to add bias.
Formula
Inputs tensors A (x) and B (weight), dequantization stride deqScale, output tensor C, dequantization processing function dequant:
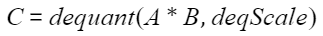
Adds a bias:
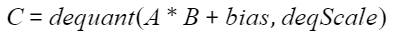
Parameters
Member |
Value Range |
Remarks |
|---|---|---|
transposeA |
false/true |
If this parameter is set to true, some scenarios are not supported. For details, see Specifications. |
transposeB |
false/true |
Varies depending on hardware. |
hasBias |
false/true |
Varies depending on hardware. |
outDataType |
ACL_FLOAT16/ACL_BF16 |
Varies depending on hardware. Data type of the output tensor. |
enAccum |
false |
- |
matmulType |
MATMUL_UNDEFINED |
- |
quantMode |
QUANT_UNDEFINED/PER_CHANNEL |
- |
Input
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
x |
[m, k]/[batch, m, k] |
int8 |
ND |
Matrix A for matrix multiplication. |
weight |
[k, n]/[batch, k, n]/[1, n / 16, k, 16]/[batch, n / 16, k, 16] |
int8 |
ND/NZ |
Weight of matrix B for matrix multiplication. |
bias |
[1, n]/[n]/[batch, n] |
int32 |
ND |
Added bias matrix. Valid when hasBias is set to true. |
deqScale |
[1, n]/[n]/[batch, n] |
int64/uint64/float |
ND |
Dequantization stride. The actually occupied memory must be 32-byte aligned. |
Output
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
output |
[m, n]/[batch, m, n] |
float16/bf16 |
ND |
Matmul and dequantization result. |
Specifications
The following table lists the combinations of input and output attributes. The combinations that are not listed in the table are not supported.
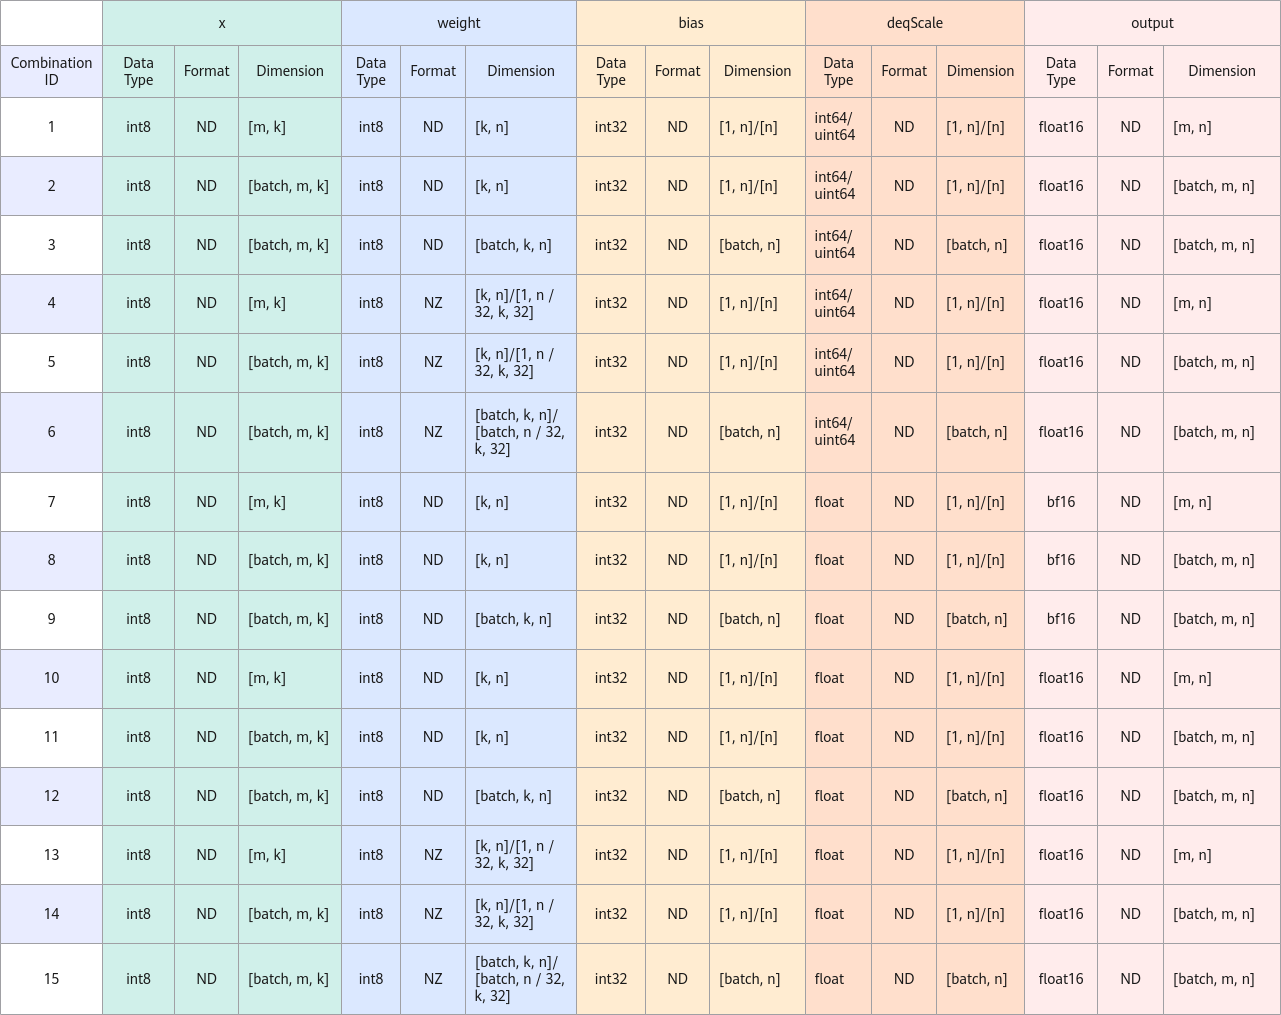
Atlas inference products : Combinations 7 to 15 are not supported.Atlas A2 training products /Atlas A2 inference products andAtlas A3 inference products /Atlas A3 training products : Combinations 10 to 15 are not supported.- When transposeA is set to true, combinations 2, 5, 8, 11, and 14 are not supported.
- When the weight has four dimensions, if transposeB is false, n is an integer multiple of 32, and k is an integer multiple of 16; if transposeB is true, k is an integer multiple of 32, and n is an integer multiple of 16.
Atlas training products : Combinations 1 to 9 are not supported.- Atlas 350 accelerator cards
- Combinations 1, 2, 4, 5, 7, and 8 are supported.
- When inTensor1 (weight) is in NZ format and one of the last two dimensions of the original ND is 1, the weightNz feature cannot be used. This API does not support this scenario.
OP Usage and Typical Scenarios
For details about how to use OP, see the usage process in Operator Usage Guide (ATB C++ APIs). For details about how to construct the Operation parameter in Single Operator, see the following parameter construction part.
// Parameter construction
atb::infer::LinearParam param;
param.transposeA = false;
param.transposeB = false;
param.hasBias = true;
param.outDataType = ACL_FLOAT16;
param.enAccum = false;
param.matmulType = MATMUL_UNDEFINED;
param.quantMode = PER_CHANNEL;
# Example
>>> x
tensor([[1, 2],
        [3, 4]])
>>> weight
tensor([[1, 2, 3],
        [4, 5, 6]])
>>> bias
tensor([1, 2, 3])
>>> deqScale
tensor([1, 2, 3])
>>> output
tensor([[10, 28, 54],
        [20, 56, 108]])
# 10 = (1 * 1 + 2 * 4 + 1) * 1
# 28 = (1 * 2 + 2 * 5 + 2) * 2
# 54 = (1 * 3 + 2 * 6 + 3) * 3
# 20 = (3 * 1 + 4 * 4 + 1) * 1
# 56 = (3 * 2 + 4 * 5 + 2) * 2
# 108 = (3 * 3 + 4 * 6 + 3) * 3