GroupedMatmulWithRoutingOperation
Applicable Products
|
Hardware Model |
Supported |
|---|---|
|
Atlas 350 accelerator cards |
x |
|
|
√ |
|
|
√ |
|
|
x |
|
|
x |
|
|
x |
Description
Multiplies the weights of top K experts by token activations in MOE. This operator does not support deterministic computing.
Application Scenarios
UP: The token value is allocated to the top K experts based on the weight of each expert.
DOWN: The computation results of top K experts are re-integrated based on the weight of each expert.
Computation Process
- UP
Formula:
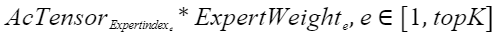
AcTensor is the activated token value, Expertindex is the expert-token index, and ExpertWeight is the expert weight. The process is as follows:
- Obtain the activated token value of the current expert from AcTensor based on
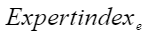 of the current expert.
- Obtain the weight of the current expert and perform BatchMatmul with the activated token value of the current expert.
- Obtain the activated token value of the current expert from AcTensor based on
- DOWN
Formula:
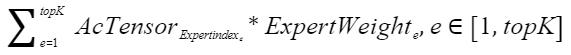
AcTensor is the activated token value, Expertindex is the expert-token index, and ExpertWeight is the expert weight. The process is as follows:
- Obtain the activated token value of the current expert from AcTensor based on
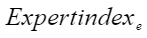 of the current expert.
- Obtain the weight of the current expert and perform BatchMatmul with the activated token value of the current expert.
- Add the results of the current token on all experts.
- Obtain the activated token value of the current expert from AcTensor based on
Definition
1 2 3 4 5 6 7 8 9 10 11 |
struct GroupedMatmulWithRoutingParam { enum GroupedMatmulType : int { GROUPED_MATMUL_UP = 0, GROUPED_MATMUL_DOWN }; bool transposeB = true; int32_t topK = 0; GroupedMatmulType groupedMatmulType = GROUPED_MATMUL_UP; aclDataType outDataType = ACL_DT_UNDEFINED; uint8_t rsv[16] = {0}; }; |
Parameters
|
Member |
Type |
Default Value |
Value Range |
Required (Yes/No) |
Description |
|---|---|---|---|---|---|
|
groupedMatmulType |
GroupedMatmulType |
GROUP_MATMUL_UP |
|
Yes |
GroupedMatmulType type:
|
|
transposeB |
bool |
true |
false/true |
No |
Whether to transpose matrix B. |
|
topK |
int32_t |
0 |
Greater than 0 |
Yes |
Number of top K experts. |
|
outDataType |
aclDataType |
ACL_DT_UNDEFINED |
|
Yes in the dequantization scenario |
|
|
rsv[16] |
uint8_t |
{0} |
[0] |
- |
Reserved |
Input and output
- UP
Non-quantization scenario
- Input
Parameter
Dimension
Data Type
Format
Description
AcTensor
[num_tokens, hidden_size_in]
float16/bf16
ND
Activation value
ExpertWeight
[num_experts, hidden_size_in, hidden_size_out]
float16/bf16
ND
Expert weight. If transposeB is set to true, the locations of hidden_size_in and hidden_size_out are exchanged.
ExpertCount
[num_experts]
int32
ND
Number of expert tokens.
Expertindex
[num_tokens*topK]
int32
ND
Expert token index.
- Output
Parameter
Dimension
Data Type
Format
Description
Result
[num_tokens*Topk, hidden_size_out]
float16/bf16
ND
Output
Quantization scenario
- Input
Parameter
Dimension
Data Type
Format
Description
AcTensor
[num_tokens, hidden_size_in]
int8
ND
Activation value
ExpertWeight
[num_experts, hidden_size_in, hidden_size_out]
int8
ND/NZ
Expert weight If transposeB is set to true, the locations of hidden_size_in and hidden_size_out are exchanged.
ExpertCount
[num_experts]
int32
ND
Number of expert tokens.
Expertindex
[num_tokens*topK]
int32
ND
Expert token index.
nscale
[num_experts, hidden_size_out]
float
ND
Dequantization coefficient in the ExpertWeight direction
mscale
[num_tokens]
float
ND
Dequantization coefficient in the AcTensor direction
- Output
Parameter
Dimension
Data Type
Format
Description
Result
[num_tokens*Topk, hidden_size_out]
float16/bf16
ND
Output
- Input
- DOWN
Non-quantization scenario
- Input
Parameter
Dimension
Data Type
Format
Description
AcTensor
[num_tokens*topK, hidden_size_in]
float16/bf16
ND
Activation value
ExpertWeight
[num_experts, hidden_size_in,hidden_size_out]
float16/bf16
ND
Expert weight If transposeB is set to true, the locations of hidden_size_in and hidden_size_out are exchanged.
ExpertCount
[num_experts]
int32
ND
Number of expert tokens.
Expertindex
[num_tokens*topK]
int32
ND
Expert token index.
- Output
Parameter
Dimension
Data Type
Format
Description
Result
[num_tokens, hidden_size_out]
float16/bf16
ND
Output
Quantization scenario
- Input
Parameter
Dimension
Data Type
Format
Description
AcTensor
[num_tokens*topK, hidden_size_in]
int8
ND
Activation value
ExpertWeight
[num_experts, hidden_size_in,hidden_size_out]
int8
ND/NZ
Expert weight. If transposeB is set to true, the locations of hidden_size_in and hidden_size_out are exchanged.
ExpertCount
[num_experts]
int32
ND
Number of expert tokens.
Expertindex
[num_tokens*topK]
int32
ND
Expert token index.
nscale
[num_experts, hidden_size_out]
float
ND
Dequantization coefficient in the ExpertWeight direction
mscale
[num_tokens*topK]
float
ND
Dequantization coefficient in the AcTensor direction
- Output
Parameter
Dimension
Data Type
Format
Description
Result
[num_tokens, hidden_size_out]
float16/bf16
ND
Output
- Input
Constraints
- If the output is quantized, the input must be of the int8 type. If the output is not quantized, the input must be of the bf16 or float16 type.
- The value of top K cannot exceed the number of experts.
- Value range of nTokens: [128, 512].
- Value range of nExperts: [128, 256].
- Value range of topK: [2, 10].
- In UP mode, the value of hiddenSizeIn is in the range of [32, 5120] and must be an integral multiple of 32. In DOWN mode, the value of hiddenSizeIn is in the range of [32, 256] and must be an integral multiple of 32.
- In UP mode, the value of hiddenSizeOut is in the range of [32, 256] and must be an integral multiple of 32. In DOWN mode, the value of hiddenSizeOut is in the range of [32, 5120] and must be an integral multiple of 32.