GenAttentionMaskOperation
Applicable Products
Product |
Supported |
|---|---|
Atlas 350 accelerator cards |
x |
√ |
|
√ |
|
x |
|
x |
|
x |
Description
Converts AttentionMask based on the actual seqlen of each batch to obtain a one-dimensional tensor.
Definition
1 2 3 4 5 | struct GenAttentionMaskParam { int32_t headNum = 1; atb::SVector<int32_t> seqLen; uint8_t rsv[8] = {0}; }; |
Parameters
Member |
Type |
Default Value |
Description |
|---|---|---|---|
headNum |
int32_t |
1 |
Number of heads in the multi-headed attention mechanism. |
seqLen |
atb::SVector<int32_t> |
- |
Actual seqlen of each batch in the unpad scenario. The number of elements is specified by batchSize. The maximum value is 32. |
rsv[8] |
uint8_t |
{0} |
Reserved |
Input and output
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
x |
[batchSize, 1, maxSeqLen, maxSeqLen] |
float16 |
ND |
Input, random matrix used for attentionmask computation. |
output |
[nSquareTokens] |
float16 |
ND |
Output, result matrix of the attentionmask computation. |
The calculation formula of nSquareTokens is as follows:
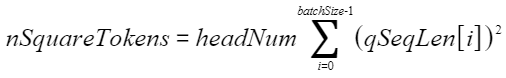
Constraints
- The length of the qSeqLen array cannot exceed 32, and each element must be greater than 0.
- The length of batchSize must be the same as that of seqLen, and the length cannot exceed 32.
- Each element in seqLen is less than or equal to maxSeqLen.