aclnnMlaPreprocess
Applicable Products
| Product | Supported |
|---|---|
| × | |
| √ | |
| √ | |
| × | |
| × | |
| × |
Function
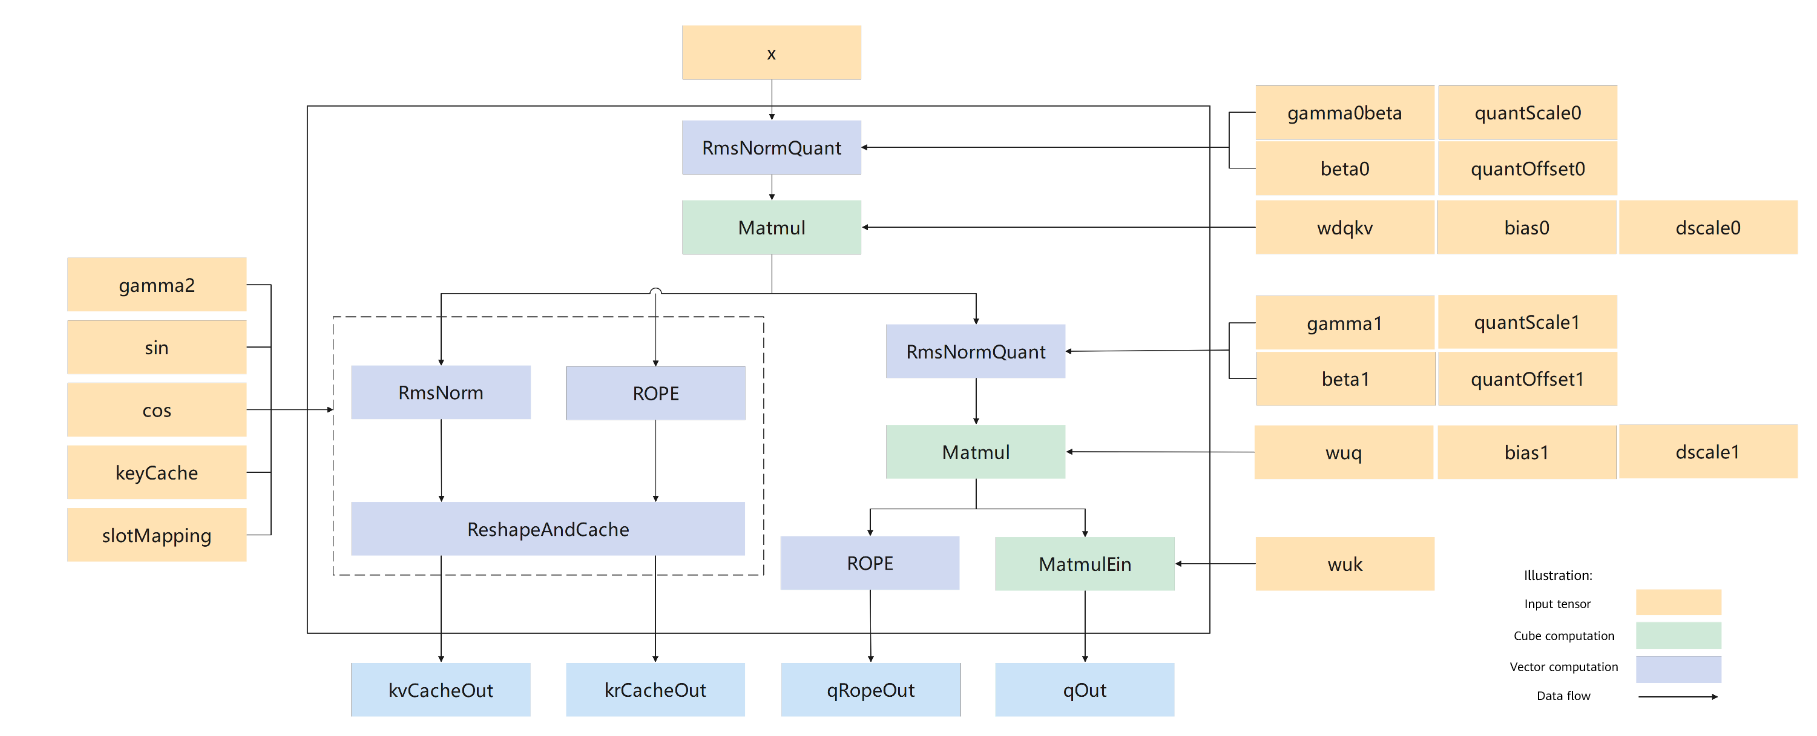
Description: In inference scenarios, preprocessing computation for Multi-Head Latent Attention. The main computation process is as follows:
First, perform RmsNormQuant on the input , multiply by , perform downsampling, and then split into path 1 and path 2.
Path 1 undergoes RmsNormQuant, is multiplied by , and then is split into path 3 and path 4.
Path 3 is multiplied by and then outputs .
Path 4 outputs after rotary position encoding.
Path 2 is split into Path 5 and Path 6.
Path 5 undergoes RmsNorm and is then passed into the Cache to obtain .
Path 6 undergoes rotary position encoding and is then passed into another Cache to obtain .
Calculation Flowchart
Formula:
RmsNormQuant Formula
Query formula, including W^{DQKV} matrix multiplication, W^{UK} matrix multiplication, RmsNormQuant, and ROPE rotary position embedding processing
Key formula, including RmsNorm and ROPE, with the computation result stored in cache
Function Prototype
Each operator is divided into a two-phase API. You must first call the "aclnnMlaPreprocessGetWorkspaceSize" API to obtain the input parameters and calculate the required workspace size based on the process, and then call the "aclnnMlaPreprocess" API to perform the computation.
aclnnStatus aclnnMlaPreprocessGetWorkspaceSize(
  const aclTensor *input,
  const aclTensor *gamma0,
  const aclTensor *beta0,
  const aclTensor *quantScale0,
  const aclTensor *quantOffset0,
  const aclTensor *wdqkv,
  const aclTensor *deScale0,
  const aclTensor *bias0,
  const aclTensor *gamma1,
  const aclTensor *beta1,
  const aclTensor *quantScale1,
  const aclTensor *quantOffset1,
  const aclTensor *wuq,
  const aclTensor *deScale1,
  const aclTensor *bias1,
  const aclTensor *gamma2,
  const aclTensor *cos,
  const aclTensor *sin,
  const aclTensor *wuk,
  const aclTensor *kvCache,
  const aclTensor *kvCacheRope,
  const aclTensor *slotMapping,
  const aclTensor *ctkvScale,
  const aclTensor *qNopeScale,
  int64_t          wdqDim,
  int64_t          qRopeDim,
  int64_t          kRopeDim,
  double           epsilon,
  int64_t          qRotaryCoeff,
  int64_t          kRotaryCoeff,
  bool             transposeWdq,
  bool             transposeWuq,
  bool             transposeWuk,
  int64_t          cacheMode,
  int64_t          quantMode,
  bool             doRmsNorm,
  int64_t          wdkvSplitCount,
  const aclTensor  *qOut,
  const aclTensor  *kvCacheOut,
  const aclTensor  *qRopeOut,
  const aclTensor  *krCacheOut,
  uint64_t        *workspaceSize,
  aclOpExecutor   **executor)
aclnnStatus aclnnMlaPreprocess(
void *workspace,
uint64_t workspaceSize,
aclOpExecutor *executor,
aclrtStream stream)aclnnMlaPreprocessGetWorkspaceSize
Parameters
Parameter Input/Output Description Instruction Data Type Data Format Dimension (Shape) Non-Contiguous Tensor input Input x used for computing Query and Key. - FLOAT16, BFLOAT16 ND [tokenNum,hiddenSize] - gamma0 Input γ parameter in the first RmsNorm computation. The data type needs to satisfy the data type deduction rule with input (see Deduction Relationship and Constraints). FLOAT16, BFLOAT16 ND [hiddenSize] - beta0 Input β parameter in the first RmsNorm calculation. The data type needs to satisfy the data type deduction rule with input (see Deduction Relationship and Constraints). FLOAT16, BFLOAT16 ND [hiddenSize] - quantScale0 Input Quantization scaling parameter in the first-time RmsNorm formula. The data type needs to satisfy the data type deduction rule with input (see Deduction Relationship and Constraints). FLOAT16, BFLOAT16 ND [1] - quantOffset0 Input Quantization offset parameter in the first-time RmsNorm formula. The data type needs to satisfy the data type deduction rule with input (see Mutual Derivation Relationship and Constraints). INT8 ND [1] - wdqkv Input Dimensionality reduction matrix for the first matrix multiplication with the input. - INT8, FLOAT16, BFLOAT16 NZ [2112,hiddenSize] - deScale0 Input Coefficient in the dimension-reduction matrix for the first matrix multiplication. When the input dtype is FLOAT16, INT64 is supported; when the input is BFLOAT16, FLOAT is supported. INT32, FLOAT ND [2112] - bias0 Input Coefficient in the dimension reduction matrix for the first matrix multiplication. Supports passing an empty tensor. Not passed when quantMode is 1 or 3. INT32 ND [2112] - gamma1 Input γ parameter in the second RmsNorm calculation. The data type needs to satisfy the data type deduction rule with input (see deduction relationship and Constraints). FLOAT16, BFLOAT16 ND [1536] - beta1 Input β parameter in the second RmsNorm calculation. The data type needs to satisfy the data type deduction rule with input (see Deduction Relationship and Constraints). FLOAT16, BFLOAT16 ND [1536] - quantScale1 Input Quantization scaling parameter in the second RmsNorm formula. The data type needs to be consistent with input and satisfy the data type deduction rule (see Deduction Relationship and Constraints). FLOAT16, BFLOAT16 ND [1] - quantOffset1 Input Quantization offset parameter in the second RmsNorm formula. The data type needs to be consistent with input and satisfy the data type deduction rules (see Deduction Relationship and Constraints). INT8 ND [1] - wuq Input Weight matrix. - INT8, FLOAT16, BFLOAT16 NZ [headNum * 192,1536] - deScale1 Input Coefficient that participates in the wuq matrix multiplication. When the input dtype is FLOAT16, INT64 is supported; when the input dtype is BFLOAT16, FLOAT is supported. INT64, FLOAT ND [headNum*192] - bias1 Input Coefficient that participates in the wuq matrix multiplication. Not passed when quantMode is 1 or 3. INT32 ND [headNum*192] - gamma2 Input Gamma parameter that participates in the RmsNormAndreshapeAndCache computation. The data type needs to satisfy the data type deduction rule with input (see Deduction Relationship and Constraints). FLOAT16, BFLOAT16 ND [512] - cos Input Sine parameter matrix used for calculation of the rotary position encoding. - FLOAT16, BFLOAT16 ND [tokenNum, 64] - sin Input Cosine parameter matrix used for calculation of rotary position encoding. - FLOAT16、BFLOAT16 ND [tokenNum,64] - wuk Input Indicates the upsampling weight for Key calculation. - Shape in ND format: [headNum, 128, 512].
- Shape in NZ format: [headNum, 32, 128, 16].
FLOAT16, BFLOAT16 ND, NZ [headNum * 192, 1536] - kvCache Input Same tensor as the output kvCacheOut. The input format varies with cacheMode: - cacheMode is 0: shape is [blockNum,blockSize,1,576], dtype is consistent with input, and the data format is ND.
- cacheMode is 1: shape is [blockNum,blockSize,1,512], the tensor shape is split, dtype is consistent with input, and the data format is ND.
- cacheMode is 2: shape is [blockNum,16,blockSize,32], dtype is int8, and the data format is NZ.
- cacheMode is 3: shape is [blockNum,32,blockSize,16], dtype is consistent with input, and the data format is NZ.
INT8, FLOAT16, BFLOAT16 ND, NZ - - kvCacheRope Input Same tensor as the output krCacheOut. Optional parameter. A null pointer can be passed. The input format varies with cacheMode: FLOAT16, BFLOAT16 ND, NZ - - slotMapping Input Indicates the index used for storing kv_cache and kr_cache. - INT32 ND [tokenNum] - ctkvScale Input Coefficient that participates in the calculation during output quantization. Passed in only when cacheMode is 2. FLOAT16, BFLOAT16 ND [1] - qNopeScale Input Coefficient that participates in the calculation during output quantization. Passed in only when cacheMode is 2. FLOAT16, BFLOAT16 ND [1] - wdqDim Input Indicates the dim size split after matmul. Reserved parameter. Currently only supports 1536. int64_t - - - qRopeDim Input Indicates the dim size of q passed to RoPE. Reserved parameter. Currently only supports 64. int64_t - - - kRopeDim Input Indicates the dim size of k passed to RoPE. Reserved parameter. Currently only supports 64. int64_t - - - epsilon Input Indicates the value added to the denominator to prevent division by zero. - double - - - qRotaryCoeff Input Indicates the q rotary coefficient. Reserved parameter. Currently only supports 2. int64_t - - - kRotaryCoeff Input Indicates the k rotary coefficient. Reserved parameter. Currently only supports 2. int64_t - - - transposeWdq Input Indicates whether wdq is transposed. Reserved parameter. Currently only supports true. bool - - - transposeWuq Input Indicates whether wuq is transposed. Reserved parameter. Currently only supports true. bool - - - transposeWuk Input Indicates whether wuk is transposed. Reserved parameter. Currently only supports true. bool - - - cacheMode Input Indicates the specified cache type. - 0: kcache and q are both output after concatenation.
- 1: The output kvCacheOut is split into kvCacheOut and krCacheOut, and qOut is split into qOut and qRopeOut.
- 2: krope and ctkv are converted to NZ format for output, and ctkv and qnope are quantized to int8 type through per_head static symmetric quantization.
- 3: krope and ctkv are converted to NZ format for output.
int64_t - - - quantMode Input Indicates the specified RmsNorm quantization type. - 0: per_tensor static asymmetric quantization, the default quantization type.
- 1: per_token dynamic symmetric quantization, not implemented.
- 2: per_token dynamic asymmetric quantization, not implemented.
- 3: no quantization, floating-point output, not implemented.
int64_t - - - doRmsNorm Input Controls whether to perform RmsNormQuant or Quant on the input tensor. - false: Only Quant is performed on the input tensor, without RmsNorm.
- true: RmsNormQuant is performed on the input tensor.
bool - - - wdkvSplitCount Input Indicates the number of wdkv splits. Supports [1-3], indicating no split, split into 2, or split into 3 dimension reduction matrices. Reserved parameter, currently only supports 1. int64_t - - - qOut Output Indicates the output tensor of Query, corresponding to the output on the right side of the computation graph after NOPE and matrix multiplication. The shape and dtype vary with cacheMode: - When cacheMode is 0: shape is [tokenNum, headNum, 576], dtype is consistent with input, and the data format is ND.
- When cacheMode is 1 or 3: shape is [tokenNum, headNum, 512], dtype is consistent with input, and the data format is ND.
- When cacheMode is 2: shape is [tokenNum, headNum, 512], dtype is INT8, and the data format is ND format.
INT8, FLOAT16, BFLOAT16 ND - - kvCacheOut Output Indicates the output of Key after ReshapeAndCache. The shape and dtype vary with cacheMode: - cacheMode is 0: shape is [blockNum, blockSize, 1, 576], dtype is consistent with input, and the data format is ND.
- cacheMode is 1: shape is [blockNum, blockSize, 1, 512], dtype is consistent with input, and the data format is ND.
- cacheMode is 2: shape is [blockNum, 16, blockSize, 32], dtype is INT8, and the data format is NZ.
- cacheMode is 3: shape is [blockNum, 32, blockSize, 16], dtype is consistent with input, and the data format is NZ.
INT8, FLOAT16, BFLOAT16 ND, NZ - - qRopeOut Output Indicates the output after rotary position encoding of Query. The shape and dtype vary with cacheMode: FLOAT16, BFLOAT16 ND - - krCacheOut Output Indicates the output of Key after ROPE and ReshapeAndCache. The shape and dtype vary with cacheMode: FLOAT16, BFLOAT16 ND, NZ - - workspaceSize Output Parameter Returns the workspace size to be applied on the Device side. - - - - - executor Output Parameter Returns the op executor, which contains the operator computation process. - - - - - Return Value
aclnnStatus: return code. For details, see aclnn Return Code.
The first-phase API performs input parameter validation and returns an error in the following scenarios:
Return Value Error Code Description ACLNN_ERR_PARAM_NULLPTR 161001 A null pointer exists in a required parameter. ACLNN_ERR_PARAM_INVALID 161002 The shape, dtype, or data type of the input parameter is not within the supported range. ACLNN_ERR_RUNTIME_ERROR 361001 An exception occurs when the API memory calls the npu runtime interface. ACLNN_ERR_INNER_TILING_ERROR 561002 A tiling exception occurs, where the dtype or shape of the input parameter is incorrect.
aclnnMlaPreprocess
Parameters
Parameter Input/Output Description workspace Input Workspace memory address applied by the Device side. workspaceSize Input Workspace size applied by the Device side, obtained by the first-phase API aclnnBatchMatMulGetWorkspaceSize. executor Input Operator executor that contains the operator computation flow. stream Input Specifies the stream for executing the task. Return Value
aclnnStatus: return code. For details, see aclnn Return Code.
Constraints
Deterministic computation:
- aclnnMlaPreprocess defaults to a deterministic implementation.
Meaning and constraints of shape format fields
tokenNum: tokenNum indicates the batch size of input samples. Value range: 0 to 256.
hiddenSize: hiddenSize indicates the size of the hidden layer, with a fixed value of 2048-10240, which is a multiple of 256.
headNum: Indicates the number of heads. Value range: 16, 32, 64, 128.
blockNum: Number of blocks in PagedAttention scenarios. Value range: 192.
blockSize: Block size in PagedAttention scenarios. Value range: 128.
When the data type of wdqkv and wuq is bfloat16, the input must also be bfloat16, hiddenSize only supports 6144, and cacheMode only supports 0 and 1.
Example
The following provides example code for reference only. For details about compilation and running, see Compile and Run Samples.
/**
 * This program is free software, you can redistribute it and/or modify.
 * Copyright (c) 2025 Huawei Technologies Co., Ltd.|Hisilicon Technologies Co., Ltd.
 * This file is a part of the CANN Open Software.
 * Licensed under CANN Open Software License Agreement Version 2.0 (the "License").
 * Please refer to the License for details. You may not use this file except in compliance with the License.
 * THIS SOFTWARE IS PROVIDED ON AN "AS IS" BASIS, WITHOUT WARRANTIES OF ANY KIND, EITHER EXPRESS OR IMPLIED, INCLUDING BUT NOT LIMITED TO NON-INFRINGEMENT, MERCHANTABILITY, OR FITNESS FOR A PARTICULAR PURPOSE.
 * See LICENSE in the root of the software repository for the full text of the License.
 */

/*!
 * \file test_aclnn_mla_preprocess.cpp
 * \brief
 */

#include <iostream>
#include <vector>
#include <sys/stat.h>
#include <fstream>
#include <fcntl.h>
#include <unistd.h>
#include <cstdio>
#include <cassert>
#include <iomanip>
#include <unistd.h>
#include "acl/acl.h"
#include "aclnn/acl_meta.h"
#include "aclnnop/aclnn_mla_preprocess.h"

#define CHECK_RET(cond, return_expr)                                           \
  do {                                                                         \
    if (!(cond)) {                                                             \
      return_expr;                                                             \
    }                                                                          \
  } while (0)

#define LOG_PRINT(message, ...)                                                \
  do {                                                                         \
    printf(message, ##__VA_ARGS__);                                            \
  } while (0)

template <typename T>
bool ReadFile(const std::string &filePath, std::vector<int64_t> shape, std::vector<T>& hostData)
{
    size_t fileSize = 1;
    for (int64_t i : shape){
        fileSize *= i;
    }
    std::ifstream file(filePath, std::ios::binary);
    if (!file.is_open()) {
        std::cerr << "Failed to open file." << std::endl;
        return 1;
    }
    // Obtain the file size.
    file.seekg(0, std::ios::end);
    file.seekg(0, std::ios::beg);
    hostData.reserve(fileSize);
    if (file.read(reinterpret_cast<char*>(hostData.data()), fileSize * sizeof(T))) {
    } else {
        std::cerr << "Failed to read file." << std::endl;
        return 1;
    }
    file.close();
    return true;
}

template <typename T>
bool WriteFile(const std::string &filePath, int64_t size, std::vector<T>& hostData)
{
    int fd = open(filePath.c_str(), O_RDWR | O_CREAT | O_TRUNC, S_IRUSR | S_IWRITE);
    if (fd < 0) {
        LOG_PRINT("Open file failed. path = %s", filePath.c_str());
        return false;
    }

    size_t writeSize = write(fd, reinterpret_cast<char*>(hostData.data()), size * sizeof(T));
    (void)close(fd);
    if (writeSize != size * sizeof(T)) {
        LOG_PRINT("Write file Failed.");
        return false;
    }

    return true;
}

int64_t GetShapeSize(const std::vector<int64_t>& shape)
{
    int64_t shapeSize = 1;
    for (auto i : shape) {
        shapeSize *= i;
    }
    return shapeSize;
}

void PrintOutResult(std::vector<int64_t>& shape, void** deviceAddr, int num)
{
    auto size = GetShapeSize(shape);
    std::vector<float> resultData(size, 0);
    auto ret = aclrtMemcpy(resultData.data(), resultData.size() * sizeof(resultData[0]), *deviceAddr,
                          size * sizeof(resultData[0]), ACL_MEMCPY_DEVICE_TO_HOST);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("copy result from device to host failed. ERROR: %d\n", ret); return);
    for (int64_t i = 0; i < 10; i++) {
        LOG_PRINT("result[%ld] is: %f\n", i, resultData[i]);
    }
}

int Init(int32_t deviceId, aclrtStream *stream) {
  // Boilerplate for resource initialization.
  auto ret = aclInit(nullptr);
  CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclInit failed. ERROR: %d\n", ret);
            return ret);
  ret = aclrtSetDevice(deviceId);
  CHECK_RET(ret == ACL_SUCCESS,
            LOG_PRINT("aclrtSetDevice failed. ERROR: %d\n", ret);
            return ret);
  ret = aclrtCreateStream(stream);
  CHECK_RET(ret == ACL_SUCCESS,
            LOG_PRINT("aclrtCreateStream failed. ERROR: %d\n", ret);
            return ret);
  return 0;
}

template <typename T>
int CreateAclTensor(const std::vector<T> &hostData,
                    const std::vector<int64_t> &shape, void **deviceAddr,
                    aclDataType dataType, aclTensor **tensor) {
  auto size = GetShapeSize(shape) * sizeof(T);
  // Call aclrtMalloc to apply for memory on the device side.
  auto ret = aclrtMalloc(deviceAddr, size, ACL_MEM_MALLOC_HUGE_FIRST);
  CHECK_RET(ret == ACL_SUCCESS,
            LOG_PRINT("aclrtMalloc failed. ERROR: %d\n", ret);
            return ret);
  // Copy host-side data to device-side memory by calling aclrtMemcpy.
  ret = aclrtMemcpy(*deviceAddr, size, hostData.data(), size,
                    ACL_MEMCPY_HOST_TO_DEVICE);
  CHECK_RET(ret == ACL_SUCCESS,
            LOG_PRINT("aclrtMemcpy failed. ERROR: %d\n", ret);
            return ret);

  // Calculate the strides of a contiguous tensor.
  std::vector<int64_t> strides(shape.size(), 1);
  for (int64_t i = shape.size() - 2; i >= 0; i--) {
    strides[i] = shape[i + 1] * strides[i + 1];
  }

  // Create an aclTensor by calling the aclCreateTensor API.
  *tensor = aclCreateTensor(shape.data(), shape.size(), dataType,
                            strides.data(), 0, aclFormat::ACL_FORMAT_ND,
                            shape.data(), shape.size(), *deviceAddr);
  return 0;
}


template <typename T>
int CreateAclTensorND(const std::vector<T>& shape, void** deviceAddr, void** hostAddr,
                    aclDataType dataType, aclTensor** tensor) {
    auto size = GetShapeSize(shape) * sizeof(T);
    // Allocate device-side memory by calling aclrtMalloc.
    auto ret = aclrtMalloc(deviceAddr, size,  ACL_MEM_MALLOC_HUGE_FIRST);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclrtMalloc ND tensor device failed. ERROR: %d\n", ret); return ret);
    // Allocate host-side memory by calling aclrtMalloc.
    ret = aclrtMalloc(hostAddr, size,   ACL_MEM_MALLOC_HUGE_FIRST);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclrtMalloc ND tensor host failed. ERROR: %d\n", ret); return ret);
    // Call aclCreateTensor to create an aclTensor.
    *tensor = aclCreateTensor(shape.data(), shape.size(), dataType, nullptr, 0, aclFormat::ACL_FORMAT_ND,
                              shape.data(), shape.size(), *deviceAddr);
    // Call aclrtMemcpy to copy data from the host side to the device side memory.
    ret = aclrtMemcpy(*deviceAddr, size, *hostAddr,   GetShapeSize(shape)*aclDataTypeSize(dataType),  ACL_MEMCPY_HOST_TO_DEVICE);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclrtMemcpy  failed. ERROR: %d\n", ret); return ret);
    return 0;
}

template <typename T>
int CreateAclTensorNZ(const std::vector<T>& shape,  void** deviceAddr, void** hostAddr,
                    aclDataType dataType, aclTensor**   tensor) {
    auto size = GetShapeSize(shape) * sizeof(T);
    // Call aclrtMalloc to apply for device side memory.
    auto ret = aclrtMalloc(deviceAddr, size,  ACL_MEM_MALLOC_HUGE_FIRST);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclrtMalloc NZ tensor device failed. ERROR: %d\n", ret); return ret);
    // Call aclrtMalloc to apply for host side memory.
    ret = aclrtMalloc(hostAddr, size,   ACL_MEM_MALLOC_HUGE_FIRST);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclrtMalloc NZ tensor device failed. ERROR: %d\n", ret); return ret);
    // Call aclCreateTensor to create an aclTensor.
    *tensor = aclCreateTensor(shape.data(), shape.size  (), dataType, nullptr, 0,   aclFormat::ACL_FORMAT_FRACTAL_NZ,
                              shape.data(), shape.size  (), *deviceAddr);
    // Call aclrtMemcpy to copy data from the host side to the device memory.
    ret = aclrtMemcpy(*deviceAddr, size, *hostAddr,   GetShapeSize(shape)*aclDataTypeSize(dataType),  ACL_MEMCPY_HOST_TO_DEVICE);
    CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("aclrtMemcpy  failed. ERROR: %d\n", ret); return ret);
    return 0;
}

int TransToNZShape(std::vector<int64_t> &shapeND, size_t  typeSize) {
    int64_t h = shapeND[0];
    int64_t w = shapeND[1];
    int64_t h0 = 16;
    int64_t w0 = 32U / typeSize;
    int64_t h1 = h / h0;
    int64_t w1 = w / w0;
    shapeND[0] = w1;
    shapeND[1] = h1;
    shapeND.emplace_back(h0);
    shapeND.emplace_back(w0);
    return 0;
}

int main() {
  // 1. (Boilerplate) Initialize device/stream. See the ACL API manual.
  // Set deviceId based on your actual device.
  int32_t deviceId = 5;
  aclrtStream stream;
  auto ret = Init(deviceId, &stream);
  CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("Init acl failed. ERROR: %d\n", ret);
            return ret);
  //Attributes
  int64_t tokenNum = 8;
  int64_t hiddenNum = 7168;
  int64_t headNum = 32;
  int64_t blockNum = 192;
  int64_t blockSize = 128;

  int64_t wdqDim = 128;
  int64_t qRopeDim = 0;
  int64_t kRopeDim = 0;
  double epsilon = 1e-05;
  int64_t qRotaryCoeff = 2;
  int64_t kRotaryCoeff = 2;
  bool transposeWdq = true;
  bool transposeWuq = true;
  bool transposeWuk = true;
  int64_t cacheMode =  1;
  int64_t quantMode =  0;
  bool doRmsNorm = true;
  int64_t wdkvSplitCount = 1;

  // 2. Construct inputs and outputs. Customize the construction based on the API.
  std::vector<int64_t> inputShape = {tokenNum, hiddenNum};
  std::vector<int64_t> gamma0Shape = {hiddenNum};
  std::vector<int64_t> beta0Shape = {hiddenNum};
  std::vector<int64_t> quantScale0Shape = {1};
  std::vector<int64_t> quantOffset0Shape = {1};
  std::vector<int64_t> wdqkvShape = {2112, hiddenNum};
  std::vector<int64_t> deScale0Shape = {2112};
  std::vector<int64_t> bias0Shape = {2112};
  std::vector<int64_t> gamma1Shape = {1536};
  std::vector<int64_t> beta1Shape = {1536};
  std::vector<int64_t> quantScale1Shape = {1};
  std::vector<int64_t> quantOffset1Shape = {1};
  std::vector<int64_t> wuqShape = {headNum * 192, 1536};
  std::vector<int64_t> deScale1Shape = {headNum * 192};
  std::vector<int64_t> bias1Shape = {headNum * 192};
  std::vector<int64_t> gamma2Shape = {512};
  std::vector<int64_t> cosShape = {tokenNum, 64};
  std::vector<int64_t> sinShape = {tokenNum, 64};
  std::vector<int64_t> wukShape = {headNum, 128, 512};
  std::vector<int64_t> kvCacheShape = {blockNum, blockSize, 1, 576};
  std::vector<int64_t> kvCacheRopeShape = {blockNum, blockSize, 1, 64};
  std::vector<int64_t> slotmappingShape = {tokenNum};
  std::vector<int64_t> ctkvScaleShape = {1};
  std::vector<int64_t> qNopeScaleShape = {headNum};

  std::vector<int64_t> qOutShape = {tokenNum, headNum, 576};
  std::vector<int64_t> kvCacheOutShape = {blockNum, blockSize, 1, 576};
  std::vector<int64_t> qRopeOutShape = {tokenNum, headNum, 64};
  std::vector<int64_t> krCacheOutShape = {blockNum, blockSize, 1, 64};

  void* inputDeviceAddr = nullptr;
  void* gamma0DeviceAddr = nullptr;
  void* beta0DeviceAddr = nullptr;
  void* quantScale0DeviceAddr = nullptr;
  void* quantOffset0DeviceAddr = nullptr;
  void* wdqkvDeviceAddr = nullptr;
  void* deScale0DeviceAddr = nullptr;
  void* bias0DeviceAddr = nullptr;
  void* gamma1DeviceAddr = nullptr;
  void* beta1DeviceAddr = nullptr;
  void* quantScale1DeviceAddr = nullptr;
  void* quantOffset1DeviceAddr = nullptr;
  void* wuqDeviceAddr = nullptr;
  void* deScale1DeviceAddr = nullptr;
  void* bias1DeviceAddr = nullptr;
  void* gamma2DeviceAddr = nullptr;
  void* cosDeviceAddr = nullptr;
  void* sinDeviceAddr = nullptr;
  void* wukDeviceAddr = nullptr;
  void* kvCacheDeviceAddr = nullptr;
  void* kvCacheRopeDeviceAddr = nullptr;
  void* slotmappingDeviceAddr = nullptr;
  void* ctkvScaleDeviceAddr = nullptr;
  void* qNopeScaleDeviceAddr = nullptr;
  void* qOutDeviceAddr = nullptr;
  void* kvCacheOutDeviceAddr = nullptr;
  void* qRopeOutDeviceAddr = nullptr;
  void* krCacheOutDeviceAddr = nullptr;

  void* inputHostAddr = nullptr;
  void* gamma0HostAddr = nullptr;
  void* beta0HostAddr = nullptr;
  void* quantScale0HostAddr = nullptr;
  void* quantOffset0HostAddr = nullptr;
  void* wdqkvHostAddr = nullptr;
  void* deScale0HostAddr = nullptr;
  void* bias0HostAddr = nullptr;
  void* gamma1HostAddr = nullptr;
  void* beta1HostAddr = nullptr;
  void* quantScale1HostAddr = nullptr;
  void* quantOffset1HostAddr = nullptr;
  void* wuqHostAddr = nullptr;
  void* deScale1HostAddr = nullptr;
  void* bias1HostAddr = nullptr;
  void* gamma2HostAddr = nullptr;
  void* cosHostAddr = nullptr;
  void* sinHostAddr = nullptr;
  void* wukHostAddr = nullptr;
  void* kvCacheHostAddr = nullptr;
  void* kvCacheRopeHostAddr = nullptr;
  void* slotmappingHostAddr = nullptr;
  void* ctkvScaleHostAddr = nullptr;
  void* qNopeScaleHostAddr = nullptr;
  void* qOutHostAddr = nullptr;
  void* kvCacheOutHostAddr = nullptr;
  void* qRopeOutHostAddr = nullptr;
  void* krCacheOutHostAddr = nullptr;

  aclTensor* input = nullptr;
  aclTensor* gamma0 = nullptr;
  aclTensor* beta0 = nullptr;
  aclTensor* quantScale0 = nullptr;
  aclTensor* quantOffset0 = nullptr;
  aclTensor* wdqkv = nullptr;
  aclTensor* deScale0 = nullptr;
  aclTensor* bias0 = nullptr;
  aclTensor* gamma1 = nullptr;
  aclTensor* beta1 = nullptr;
  aclTensor* quantScale1 = nullptr;
  aclTensor* quantOffset1 = nullptr;
  aclTensor* wuq = nullptr;
  aclTensor* deScale1 = nullptr;
  aclTensor* bias1 = nullptr;
  aclTensor* gamma2 = nullptr;
  aclTensor* cos = nullptr;
  aclTensor* sin = nullptr;
  aclTensor* wuk = nullptr;
  aclTensor* kvCache = nullptr;
  aclTensor* kvCacheRope = nullptr;
  aclTensor* slotmapping = nullptr;
  aclTensor* ctkvScale = nullptr;
  aclTensor* qNopeScale = nullptr;
  aclTensor* qOut = nullptr;
  aclTensor* kvCacheOut = nullptr;
  aclTensor* qRopeOut = nullptr;
  aclTensor* krCacheOut = nullptr;

  // Convert the shapes of three NZ format variables.
  ret = TransToNZShape(wdqkvShape, sizeof(int8_t));
  CHECK_RET(ret == 0, LOG_PRINT("trans NZ shape failed. \n"); return ret);
  ret = TransToNZShape(wuqShape, sizeof  (int8_t));
  CHECK_RET(ret == 0, LOG_PRINT("trans NZ shape failed. \n"); return ret);

  ret = CreateAclTensorND(inputShape, &inputDeviceAddr, &inputHostAddr, aclDataType::ACL_FLOAT16, &input);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(gamma0Shape, &gamma0DeviceAddr, &gamma0HostAddr, aclDataType::ACL_FLOAT16, &gamma0);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(beta0Shape, &beta0DeviceAddr, &beta0HostAddr, aclDataType::ACL_FLOAT16, &beta0);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(quantScale0Shape, &quantScale0DeviceAddr, &quantScale0HostAddr, aclDataType::ACL_FLOAT16, &quantScale0);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(quantOffset0Shape, &quantOffset0DeviceAddr, &quantOffset0HostAddr, aclDataType::ACL_INT8, &quantOffset0);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  //Convert wdqkv to NZ.
  ret = CreateAclTensorNZ(wdqkvShape, &wdqkvDeviceAddr, &wdqkvHostAddr, aclDataType::ACL_INT8, &wdqkv);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  //If the input is fp16, convert it to int64 here.
  ret = CreateAclTensorND(deScale0Shape, &deScale0DeviceAddr, &deScale0HostAddr, aclDataType::ACL_INT64, &deScale0);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(bias0Shape, &bias0DeviceAddr, &bias0HostAddr, aclDataType::ACL_INT32, &bias0);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(gamma1Shape, &gamma1DeviceAddr, &gamma1HostAddr, aclDataType::ACL_FLOAT16, &gamma1);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(beta1Shape, &beta1DeviceAddr, &beta1HostAddr, aclDataType::ACL_FLOAT16, &beta1);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(quantScale1Shape, &quantScale1DeviceAddr, &quantScale1HostAddr, aclDataType::ACL_FLOAT16, &quantScale1);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(quantOffset1Shape, &quantOffset1DeviceAddr, &quantOffset1HostAddr, aclDataType::ACL_INT8, &quantOffset1);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  //Convert wuq to NZ.
  ret = CreateAclTensorNZ(wuqShape, &wuqDeviceAddr, &wuqHostAddr, aclDataType::ACL_INT8, &wuq);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  //If the input is fp16, convert it to int64 here.
  ret = CreateAclTensorND(deScale1Shape, &deScale1DeviceAddr, &deScale1HostAddr, aclDataType::ACL_INT64, &deScale1);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(bias1Shape, &bias1DeviceAddr, &bias1HostAddr, aclDataType::ACL_INT32, &bias1);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(gamma2Shape, &gamma2DeviceAddr, &gamma2HostAddr, aclDataType::ACL_FLOAT16, &gamma2);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(cosShape, &cosDeviceAddr, &cosHostAddr, aclDataType::ACL_FLOAT16, &cos);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(sinShape, &sinDeviceAddr, &sinHostAddr, aclDataType::ACL_FLOAT16, &sin);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(wukShape, &wukDeviceAddr, &wukHostAddr, aclDataType::ACL_FLOAT16, &wuk);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(kvCacheShape, &kvCacheDeviceAddr, &kvCacheHostAddr, aclDataType::ACL_FLOAT16, &kvCache);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(kvCacheRopeShape, &kvCacheRopeDeviceAddr, &kvCacheRopeHostAddr, aclDataType::ACL_FLOAT16, &kvCacheRope);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(slotmappingShape, &slotmappingDeviceAddr, &slotmappingHostAddr, aclDataType::ACL_INT32, &slotmapping);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(ctkvScaleShape, &ctkvScaleDeviceAddr, &ctkvScaleHostAddr, aclDataType::ACL_FLOAT16, &ctkvScale);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(qNopeScaleShape, &qNopeScaleDeviceAddr, &qNopeScaleHostAddr, aclDataType::ACL_FLOAT16, &qNopeScale);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(qOutShape, &qOutDeviceAddr, &qOutHostAddr, aclDataType::ACL_FLOAT16, &qOut);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(kvCacheOutShape, &kvCacheOutDeviceAddr, &kvCacheOutHostAddr, aclDataType::ACL_FLOAT16, &kvCacheOut);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(qRopeOutShape, &qRopeOutDeviceAddr, &qRopeOutHostAddr, aclDataType::ACL_FLOAT16, &qRopeOut);
  CHECK_RET(ret == ACL_SUCCESS, return ret);
  ret = CreateAclTensorND(krCacheOutShape, &krCacheOutDeviceAddr, &krCacheOutHostAddr, aclDataType::ACL_FLOAT16, &krCacheOut);
  CHECK_RET(ret == ACL_SUCCESS, return ret);

  // 3. Call the CANN operator library API. Replace it with the specific API name.
  uint64_t workspaceSize = 0;
  aclOpExecutor *executor;

  // Call the first-phase API of aclnnMlaPreprocess.
  ret = aclnnMlaPreprocessGetWorkspaceSize(
    input, gamma0, beta0, quantScale0, quantOffset0,
    wdqkv, deScale0, bias0, gamma1, beta1, quantScale1, quantOffset1, wuq, deScale1, bias1, gamma2, cos, sin, wuk, kvCache, kvCacheRope, slotmapping, ctkvScale, qNopeScale,
    wdqDim, qRopeDim, kRopeDim, epsilon, qRotaryCoeff, kRotaryCoeff, transposeWdq, transposeWuq, transposeWuk, cacheMode, quantMode, doRmsNorm, wdkvSplitCount, qOut, kvCacheOut, qRopeOut, krCacheOut, &workspaceSize, &executor);
  CHECK_RET(
      ret == ACL_SUCCESS,
      LOG_PRINT("acaclnnMlaPreprocessGetWorkspaceSize failed. ERROR: %d\n", ret);
      return ret);

  // Apply for device memory based on the workspaceSize calculated by the first-phase API.
  void *workspaceAddr = nullptr;
  if (workspaceSize > 0) {
    ret = aclrtMalloc(&workspaceAddr, workspaceSize, ACL_MEM_MALLOC_HUGE_FIRST);
    CHECK_RET(ret == ACL_SUCCESS,
              LOG_PRINT("allocate workspace failed. ERROR: %d\n", ret);
              return ret);
  }

  // Call the second-phase API of aclnnMlaPreprocess.
  ret = aclnnMlaPreprocess(workspaceAddr, workspaceSize, executor, stream);
  CHECK_RET(ret == ACL_SUCCESS,
            LOG_PRINT("acaclnnMlaPreprocess failed. ERROR: %d\n", ret);
            return ret);

  // 4. (Boilerplate) Synchronize and wait for task execution to complete.
  ret = aclrtSynchronizeStream(stream);
  CHECK_RET(ret == ACL_SUCCESS,
            LOG_PRINT("aclrtSynchronizeStream failed. ERROR: %d\n", ret);
            return ret);

  // 5. Obtain the output value and copy the result from the device-side memory to the host side. Modify based on the specific API definition.
  auto qOutSize = GetShapeSize(qOutShape);
  std::vector<float> qOutData(qOutSize, 0);
  ret = aclrtMemcpy(qOutData.data(), qOutData.size() * sizeof(qOutData[0]), qOutDeviceAddr, qOutSize * sizeof(float),
                    ACL_MEMCPY_DEVICE_TO_HOST);
  CHECK_RET(ret == ACL_SUCCESS, LOG_PRINT("copy result from device to host failed. ERROR: %d\n", ret); return ret);

  // 6. Release aclTensor and aclScalar. Modify based on the specific API definition.
  // Release aclTensor resources.
  aclDestroyTensor(input);
  aclDestroyTensor(gamma0);
  aclDestroyTensor(beta0);
  aclDestroyTensor(quantScale0);
  aclDestroyTensor(quantOffset0);
  aclDestroyTensor(wdqkv);
  aclDestroyTensor(deScale0);
  aclDestroyTensor(bias0);
  aclDestroyTensor(gamma1);
  aclDestroyTensor(beta1);
  aclDestroyTensor(quantScale1);
  aclDestroyTensor(quantOffset1);
  aclDestroyTensor(wuq);
  aclDestroyTensor(deScale1);
  aclDestroyTensor(bias1);
  aclDestroyTensor(gamma2);
  aclDestroyTensor(cos);
  aclDestroyTensor(sin);
  aclDestroyTensor(wuk);
  aclDestroyTensor(kvCache);
  aclDestroyTensor(kvCacheRope);
  aclDestroyTensor(slotmapping);
  aclDestroyTensor(ctkvScale);
  aclDestroyTensor(qNopeScale);

  // 7. Release device resources.
  aclrtFree(inputDeviceAddr);
  aclrtFree(gamma0DeviceAddr);
  aclrtFree(beta0DeviceAddr);
  aclrtFree(quantScale0DeviceAddr);
  aclrtFree(quantOffset0DeviceAddr);
  aclrtFree(wdqkvDeviceAddr);
  aclrtFree(deScale0DeviceAddr);
  aclrtFree(bias0DeviceAddr);
  aclrtFree(gamma1DeviceAddr);
  aclrtFree(beta1DeviceAddr);
  aclrtFree(quantScale1DeviceAddr);
  aclrtFree(quantOffset1DeviceAddr);
  aclrtFree(wuqDeviceAddr);
  aclrtFree(deScale1DeviceAddr);
  aclrtFree(bias1DeviceAddr);
  aclrtFree(gamma2DeviceAddr);
  aclrtFree(cosDeviceAddr);
  aclrtFree(sinDeviceAddr);
  aclrtFree(wukDeviceAddr);
  aclrtFree(kvCacheDeviceAddr);
  aclrtFree(kvCacheRopeDeviceAddr);
  aclrtFree(slotmappingDeviceAddr);
  aclrtFree(ctkvScaleDeviceAddr);
  aclrtFree(qNopeScaleDeviceAddr);

  // 8. Release host resources.
  aclrtFree(inputHostAddr);
  aclrtFree(gamma0HostAddr);
  aclrtFree(beta0HostAddr);
  aclrtFree(quantScale0HostAddr);
  aclrtFree(quantOffset0HostAddr);
  aclrtFree(wdqkvHostAddr);
  aclrtFree(deScale0HostAddr);
  aclrtFree(bias0HostAddr);
  aclrtFree(gamma1HostAddr);
  aclrtFree(beta1HostAddr);
  aclrtFree(quantScale1HostAddr);
  aclrtFree(quantOffset1HostAddr);
  aclrtFree(wuqHostAddr);
  aclrtFree(deScale1HostAddr);
  aclrtFree(bias1HostAddr);
  aclrtFree(gamma2HostAddr);
  aclrtFree(cosHostAddr);
  aclrtFree(sinHostAddr);
  aclrtFree(wukHostAddr);
  aclrtFree(kvCacheHostAddr);
  aclrtFree(kvCacheRopeHostAddr);
  aclrtFree(slotmappingHostAddr);
  aclrtFree(ctkvScaleHostAddr);
  aclrtFree(qNopeScaleHostAddr);
  if (workspaceSize > 0) {
    aclrtFree(workspaceAddr);
  }
  aclrtDestroyStream(stream);
  aclrtResetDevice(deviceId);
  aclFinalize();

  return 0;
}