Formula
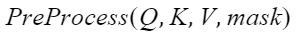
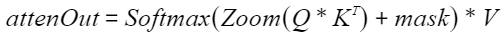
PreProcess is the prologue of Q, K, V, and mask. For example, enabling dequantization fusion requires dequantization on the inputs K and V before calculation.
attenOut is calculated using attention. Zoom is the scaling of  . In the standard calculation process, 1/sqrt(head_size) is multiplied. When logN is enabled, the logN coefficient is multiplied.
Parent topic: PagedAttentionOperation