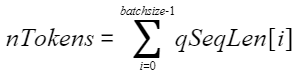RopeGradOperation
Applicable Products
Product |
Supported |
|---|---|
Atlas 350 accelerator cards |
x |
√ |
|
√ |
|
x |
|
x |
|
x |
Description
Implements backward rotary position embedding.
Train the operator to implement gradient backward computation for RoPE. The computation process is as follows:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 | def RopeGradCalc(self, in_tensors): cos_list = [in_tensors[2][:x, :] for x in OP_PARAM['qSeqLen']] sin_list = [in_tensors[3][:x, :] for x in OP_PARAM['qSeqLen']] cos = torch.cat(cos_list, dim=0) sin = torch.cat(sin_list, dim=0) sin1 = sin[:,:64] sin2 = sin[:,64:] rohqgsin = torch.cat((sin2, -sin1), dim=-1) q_grad = torch.zeros_like(in_tensors[0]) bs = int(in_tensors[0].shape[1] / 128) for i in range(bs): q_grad[:, i * 128:(i + 1) * 128] = in_tensors[0][:, i * 128:(i + 1) * 128] * (cos + rohqgsin) k_grad = torch.zeros_like(in_tensors[1]) for i in range(bs): k_grad[:,i * 128:(i + 1) * 128] = in_tensors[1][:, i * 128:(i + 1) * 128] *(cos + rohqgsin) return [q_grad, k_grad] |
Definition
1 2 3 4 | struct RopeGradParam { std::vector<int32_t> qSeqLen; uint8_t rsv[8] = {0}; }; |
Parameters
Member |
Type |
Default Value |
Description |
|---|---|---|---|
qSeqLen |
std::vector< int32_t > |
- |
Actual seqlen of each batch in the unpad scenario. The size cannot be 0. The value of qSeqLen can only be [2,1,4,4]. |
rsv[8] |
uint8_t |
{0} |
Reserved |
Unpad scenario: When the input sequence length (seq length) is dynamic, if all input sequences are calculated based on the maximum length, a large number of redundant calculations exist. In the unpad solution, the sequence length is calculated based on the actual length instead of the maximum length in the decoder process, reducing the calculation workload.
Input
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
ropeQ_grad1 |
[nTokens, hiddenSize] |
float16 |
ND |
ropeQ_grad matrix. |
ropeQ_grad2 |
[nTokens, hiddenSize] |
float16 |
ND |
ropeQ_grad matrix. |
cos |
[maxSeqLen, head_size] |
float16 |
ND |
cos matrix. maxSeqLen is the largest element in qSeqLen, and head_size is 128. |
sin |
[maxSeqLen, head_size] |
float16 |
ND |
sin matrix. |
Output
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
q_grad |
[nTokens, hiddenSize] |
float16 |
ND |
q_grad matrix. |
k_grad |
[nTokens, hiddenSize] |
float16 |
ND |
k_grad matrix. |