KVCacheOperation
Applicable Products
|
Hardware Model |
Supported |
|---|---|
|
Atlas 350 accelerator cards |
x |
|
|
√ |
|
|
√ |
|
|
x |
|
|
x |
|
|
x |
Description
Implements KVCache processing.
For each batch:
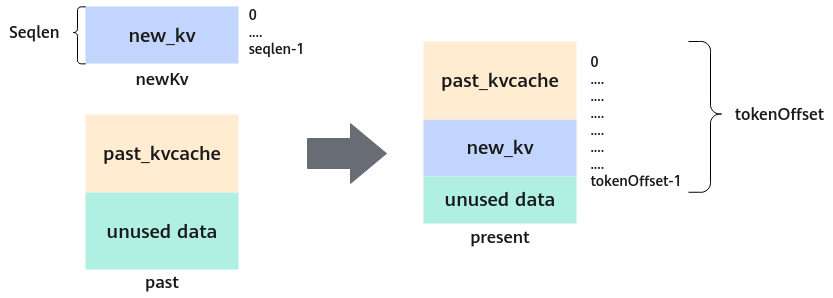
Compute logic:
prefix_ntokens = 0
for i in range(batch):
    for j in range(seqlen[i]):
        cache_out[layer_id[0]][i][token_offset[i] - seqlen[i] + j][:] = newkv[prefix_ntokens + j][:] # Modifies only the cache content of the layer specified by layer_id.
    prefix_ntokens += seqlen[i]
Operator Context
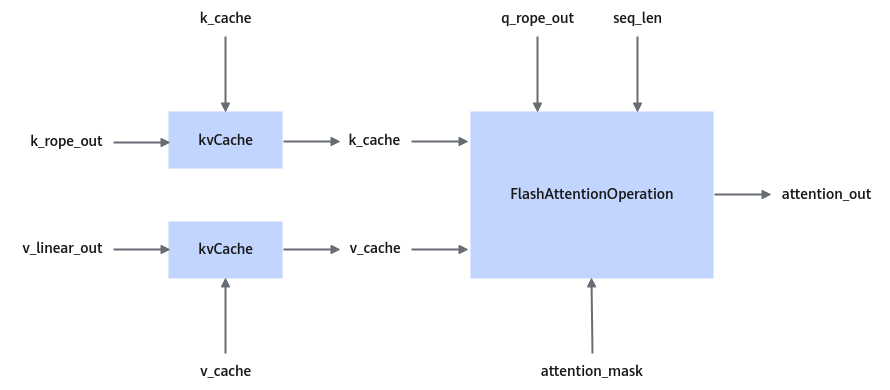
Stores k and v in kcache and vcache. This function is used in the selfattention operator.
Application Scenarios
Used in the transformer inference phase.
For example, if a user enters "the world's highest peak" and the model continues to write "is Mount Everest," the computation process of each step of KV Cache is as follows:
- Step 1: The cache K and cache V are empty, and the input is "the world's highest peak", which is considered as three words. The model performs parallel computing in the common way.
- Obtain k, v, and an attention representation
 corresponding to each token through parallel computing.
- Use
 to predict the next token and obtain "is".
- Update the cache by setting
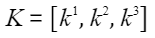 and
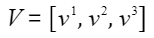 .
- Obtain k, v, and an attention representation
- Step 2:
- Input "is" into the model, and map the word vector to obtain
 ,
 , and
 .
- Update the cache by setting
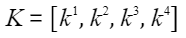 and
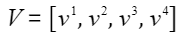 .
- Perform
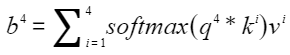 and predict the next token and obtain "Mount".
- Input "is" into the model, and map the word vector to obtain
Definition
1 2 3 |
struct KVCacheParam { uint8_t rsv[8] = {0}; }; |
Parameters
|
Member |
Type |
Default Value |
Description |
|---|---|---|---|
|
rsv[8] |
uint8_t |
{0} |
Reserved |
Input
|
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
|
newKv |
|
float16/int8 |
ND |
Key or value to be cached When the dimension is 4D, headNum multiplied by headSize must be equal to hiddenSize. |
|
layerId |
[1] |
int32 |
ND |
Layer to be cached. The operator modifies only the cache content of the layer specified by layer_id in past. |
|
past |
[layer, batch, maxSeqLen, hiddenSize] |
float16/int8 Same as that of newKv |
ND |
Historical key or value that has been cached. |
|
tokenOffset |
[batch] |
int32 |
ND |
Token offset after cache is performed in each batch. |
|
seqLen |
[batch] |
int32 |
ND |
seqLen of newKv in each batch. |
Output
|
Parameter |
Dimension |
Data Type |
Format |
Description |
|---|---|---|---|---|
|
present |
[layer, batch, maxSeqLen, hiddenSize] |
float16/int8 |
ND |
Cached key or value. The output present and input past point to the same address, that is, the in-place modification is performed. The data type and format must be the same as those of newkv. |
Constraints
- The number of elements in seqLen array is greater than 0, and the sum of arrays is nTokens.
- The number of elements in the tokenOffset array is greater than 0 and less than the value of maxSeqLen.
- The value of layerId must be smaller than the first dimension of past.
- The value of hiddenSize must be 32-byte aligned.