aclrtDevAttr
|
Data Format |
Description |
|---|---|
|
ACL_DEV_ATTR_AICPU_CORE_NUM = 1 |
Number of AI CPUs. |
|
ACL_DEV_ATTR_AICORE_CORE_NUM = 101 |
Number of AI Cores. |
|
ACL_DEV_ATTR_VECTOR_CORE_NUM = 201 |
Number of vector cores. |
|
ACL_DEV_ATTR_WARP_SIZE = 202 |
Number of threads in a warp. In the Single Instruction Multiple Thread (SIMT) programming model, a warp is a set of threads that execute the same instruction. This type is supported only by the |
|
ACL_DEV_ATTR_MAX_THREAD_PER_VECTOR_CORE = 203 |
Maximum number of threads that can reside on each Vector Core at the same time. This type is supported only by the |
|
ACL_DEV_ATTR_LOCAL_MEM_PER_VECTOR_CORE = 204 |
Maximum local memory that can be used on each Vector Core, in bytes. This type is supported only by the |
|
ACL_DEV_ATTR_MAX_GRID_DIM_X = 205 |
Maximum value of the grid dimension X, used for grid configuration of thread blocks in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_GRID_DIM_Y = 206 |
Maximum value of the grid dimension Y, used for grid configuration of thread blocks in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_GRID_DIM_Z = 207 |
Maximum value of the grid dimension Z, used for grid configuration of thread blocks in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_BLOCK_PER_GRID = 208 |
Maximum number of blocks in each grid, used for grid configuration of thread blocks in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_THREADS_PER_BLOCK = 209 |
Maximum number of threads in each block, used for grid configuration of thread blocks in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_BLOCK_DIM_X = 210 |
Maximum value of the block dimension X, used for thread block configuration in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_BLOCK_DIM_Y = 211 |
Maximum value of the block dimension Y, used for thread block configuration in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_MAX_BLOCK_DIM_Z = 212 |
Maximum value of the block dimension Z, used for thread block configuration in the SIMT programming model. Only the For product models that do not support this option, 0 is returned by default. |
|
ACL_DEV_ATTR_TOTAL_GLOBAL_MEM_SIZE = 301 |
Total available memory on the device, in bytes. |
|
ACL_DEV_ATTR_L2_CACHE_SIZE = 302 |
L2 cache size, in bytes. |
|
ACL_DEV_ATTR_SMP_ID = 401 |
Symmetric multiprocessing (SMP) ID, which is used to identify whether devices run on the same operating system. |
|
ACL_DEV_ATTR_PHY_CHIP_ID = 402 |
Physical chip ID. |
|
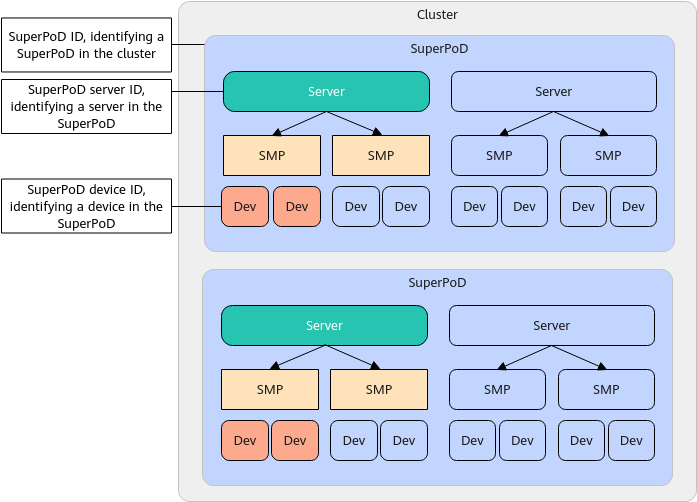
ACL_DEV_ATTR_SUPER_POD_DEVICE_ID = 403 |
SuperPOD device ID, which indicates the device ID in the supernode product. |
|
ACL_DEV_ATTR_SUPER_POD_SERVER_ID = 404 |
SuperPOD server ID, which indicates the server ID in the supernode product. |
|
ACL_DEV_ATTR_SUPER_POD_ID = 405 |
SuperPOD ID, which indicates the supernode ID in the cluster. |
|
ACL_DEV_ATTR_CUST_OP_PRIVILEGE = 406 |
Whether the custom operator can execute more system call permissions. The options are as follows:
The |
|
ACL_DEV_ATTR_MAINBOARD_ID = 407 |
Mainboard ID. |
|
ACL_DEV_ATTR_HD_CONNECT_TYPE = 408 |
Interconnection protocol between the host and device. The options are as follows:
This option is supported only for For product models that do not support this option, an error is returned. |
|
ACL_DEV_ATTR_DEVICE_FORM_FACTOR = 409 |
Device form. The options are as follows:
This option is supported only for |
|
ACL_DEV_ATTR_IS_VIRTUAL = 501 |
Whether the Ascend virtual instance is used.
|
|
ACL_DEV_ATTR_NPU_ARCH = 601 |
NPU architecture version. The mapping between product models and NPU architecture versions is as follows:
|
Relationships Between AI Cores, Cube Cores, and Vector Cores
The definition of a Core helps you better understand the relationships between AI Cores, Cube Cores, and Vector Cores. A Core is a compute core with an independent Scalar compute unit. Generally, the Scalar compute unit provides multiple functions for the compute core, such as the single instruction multiple data (SIMD) instruction dispatch. Therefore, the Scalar compute unit is also called the intra-core scheduling unit. The AI data processing core unit varies with products. Currently, there are the following types:
- The AI data processing core unit is an AI Core.
- In an AI Core, a Cube and a Vector share a Scalar scheduling unit, for example,
Atlas training products .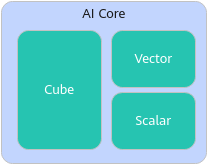
- In an AI Core, a Cube and a Vector have their own Scalar scheduling units, which are also called a Cube Core and a Vector Core. In this case, a Cube Core and a group of Vector Cores are defined as an AI Core. The number of AI Cores is usually calculated based on the number of Cube Cores, for example,
Atlas A2 training products /Atlas A2 inference products .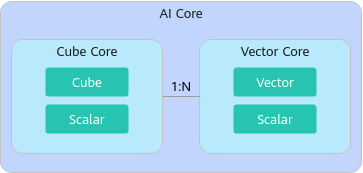
- In an AI Core, a Cube and a Vector share a Scalar scheduling unit, for example,
- The AI data processing core units are AI Cores and independent Vector Cores. The AI Cores and Vector Cores have independent Scalar scheduling units, for example,
Atlas inference products .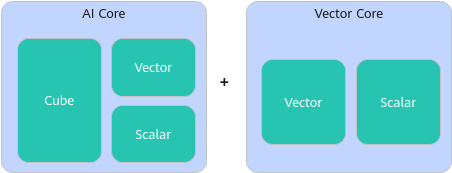
Relationships Between SuperPoD IDs, SuperPoD Server IDs, and SuperPoD Device IDs