功能描述
实现“Transformer Attention Score”的融合计算,实现的计算公式如下:
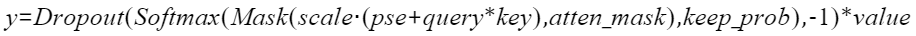
接口原型
torch_npu.npu_fusion_attention(Tensor query, Tensor key, Tensor value, int head_num, str input_layout, Tensor? pse=None, Tensor? padding_mask=None, Tensor? atten_mask=None, float scale=1., float keep_prob=1., int pre_tockens=2147483647, int next_tockens=2147483647, int inner_precise=1, int[]? prefix=None, int sparse_mode=0, bool gen_mask_parallel=True, bool sync=False ) -> (Tensor, Tensor, Tensor, Tensor, int, int, int)
参数说明
- query:Device侧的Tensor,公式中输入Q,数据类型支持FLOAT16、BFLOAT16,数据格式支持ND。综合约束请见约束说明。
- key:Device侧的Tensor,公式中输入K,数据类型支持FLOAT16、BFLOAT16,数据格式支持ND。综合约束请见约束说明。
- value:Device侧的Tensor,公式中输入V,数据类型支持FLOAT16、BFLOAT16,数据格式支持ND。综合约束请见约束说明。
- head_num:Host侧的int64_t,代表head个数,数据类型支持INT64。综合约束请见约束说明。
- input_layout:Host侧的string,代表输入query、key、value的数据排布格式,支持BSH、SBH、BSND、BNSD。后续章节如无特殊说明,S表示query或key、value的sequence length,Sq表示query的sequence length,Skv表示key、value的sequence length,SS表示Sq*Skv。
- pse:Device侧的Tensor,公式中输入pse,可选参数,表示位置编码。数据类型支持FLOAT16、BFLOAT16,数据格式支持ND。四维输入,参数每个batch不相同,BNSS格式;每个batch相同,1NSS格式。
- padding_mask:Device侧的Tensor,暂不支持该参数。
- atten_mask:Device侧的Tensor,可选参数,取值为1代表该位不参与计算(不生效),为0代表该位参与计算,数据类型支持BOOL,数据格式支持ND格式,输入shape类型支持BNSS格式、B1SS格式、11SS格式、SS格式。综合约束请见约束说明。
- scale:Host侧的double,公式中d开根号的倒数,代表缩放系数,作为计算流中Muls的scalar值,数据类型支持DOUBLE,默认值为1。
- keep_prob:Host侧的double,可选参数,代表dropMask中1的比例,数据类型支持DOUBLE,默认值为1,表示全部保留。
- pre_tockens:Host侧的int,用于稀疏计算的参数,可选参数,数据类型支持INT64,默认值为2147483647。综合约束请见约束说明。
- next_tockens:Host侧的int,用于稀疏计算的参数,可选参数,数据类型支持INT64,默认值为2147483647。next_tockens和pre_tockens取值与atten_mask的关系请参见sparse_mode参数,参数取值与atten_mask分布不一致会导致精度问题。综合约束请见约束说明。
- inner_precise:Host侧的int,数据类型支持INT64,保留参数,暂未使用。
- prefix:Host侧的int array,可选参数,代表prefix稀疏计算场景每个Batch的N值,暂不支持该参数。
- sparse_mode:Host侧的int,表示sparse的模式,可选参数。数据类型支持:INT64,默认值为0,支持配置值为0、1、2、3、4。当整网的atten_mask都相同且shape小于2048*2048时,建议使用defaultMask模式,来减少内存使用量。综合约束请见约束说明。
sparse_mode
含义
备注
0
defaultMask模式
-
1
allMask模式
-
2
leftUpCausal模式
-
3
rightDownCausal模式
-
4
band模式
-
atten_mask的工作原理为,在Mask为True的位置遮蔽query(Q)与key(K)的转置矩阵乘积的值,示意如下:
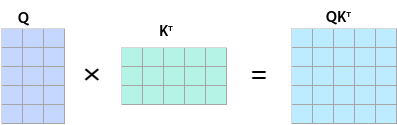
QKT矩阵在atten_mask为Ture的位置会被遮蔽,效果如下:
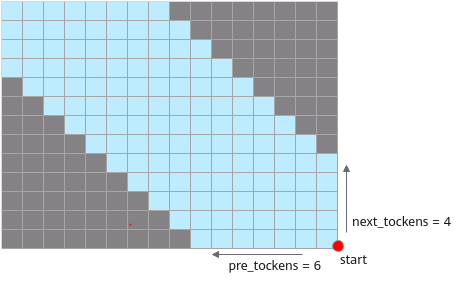
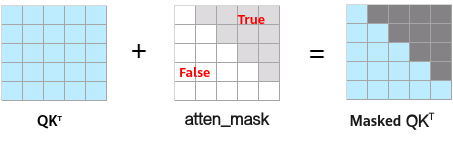 说明:下图中的蓝色表示保留该值,atten_mask中,应该配置为False;阴影表示遮蔽该值,atten_mask中应配置为True。
- sparse_mode为0时,代表defaultMask模式。
- 不传mask:如果atten_mask未传入则不做mask操作,atten_mask取值为None,忽略pre_tockens和next_tockens取值。Masked QKT矩阵示意如下:
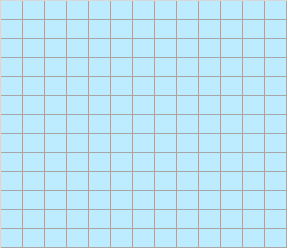
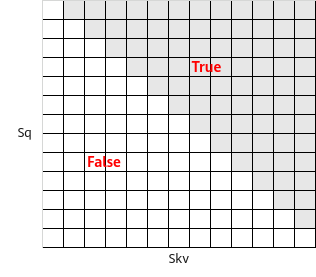
- next_tockens取值为0,pre_tockens取值大于等于Sq时,表示causal场景sparse,atten_mask应传入下三角矩阵,此时pre_tockens和next_tockens之间的部分需要计算,Masked QKT矩阵示意如下:
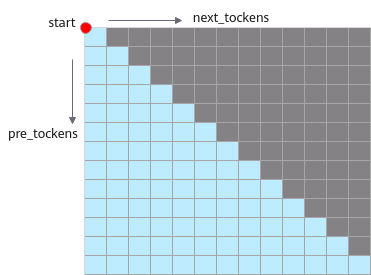
atten_mask应传入下三角矩阵,示意如下:
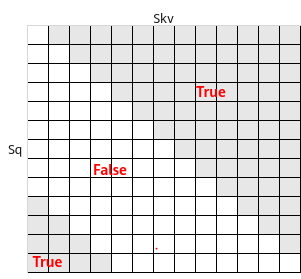
- pre_tockens小于Sq,next_tockens小于Skv,且都大于等于0时,表示band场景,此时pre_tockens和next_tockens之间的部分需要计算。Masked QKT矩阵示意如下:
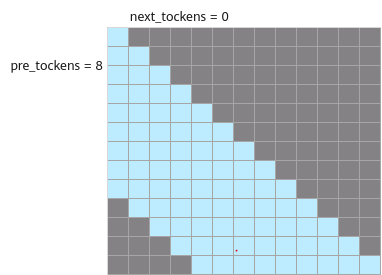
atten_mask应传入band形状矩阵,示意如下:
- 不传mask:如果atten_mask未传入则不做mask操作,atten_mask取值为None,忽略pre_tockens和next_tockens取值。Masked QKT矩阵示意如下:
- sparse_mode为1时,代表allMask,即传入完整的atten_mask矩阵。
该场景下忽略next_tockens、pre_tockens取值,Masked QKT矩阵示意如下:
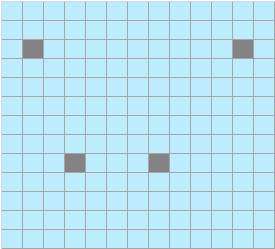
- sparse_mode为2时,代表leftUpCausal模式的mask,对应以左上顶点划分的下三角场景(参数起点为左上角)。该场景下忽略next_tockens、pre_tockens取值,Masked QKT矩阵示意如下:
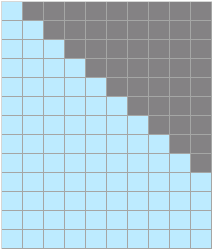
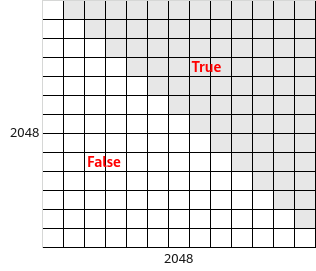
传入的atten_mask为优化后的压缩下三角矩阵(2048*2048),压缩下三角矩阵示意(下同):
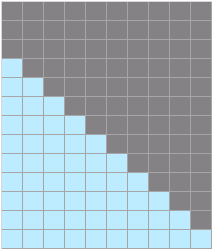
- sparse_mode为3时,代表rightDownCausal模式的mask,对应以右下顶点划分的下三角场景(参数起点为右下角)。该场景下忽略next_tockens、pre_tockens取值。atten_mask为优化后的压缩下三角矩阵(2048*2048),Masked QKT矩阵示意如下:
- sparse_mode为4时,代表band场景,即计算pre_tockens和next_tockens之间的部分,参数起点为右下角,pre_tockens和next_tockens之间需要有交集, atten_mask应传入band形状矩阵。
- sparse_mode为0时,代表defaultMask模式。
- gen_mask_parallel:debug参数,DSA生成dropout随机数向量mask的控制开关,默认值为True:同AI Core计算并行,False:同AI Core计算串行。
- sync:debug参数,DSA生成dropout随机数向量mask的控制开关,默认值为False:dropout mask异步生成,True:dropout mask同步生成。
输出说明
共7个输出
(Tensor, Tensor, Tensor, Tensor, int, int, int)
- 第1个输出为Tensor,计算公式的最终输出y。
- 第2个输出为Tensor,Softmax 计算的Max中间结果,用于反向计算。
- 第3个输出为Tensor,Softmax计算的Sum中间结果,用于反向计算。
- 第4个输出为Tensor,保留参数,暂未使用。
- 第5个输出为int,DSA生成dropoutmask中,Philox算法的seed。
- 第6个输出为int,DSA生成dropoutmask中,Philox算法的offset。
- 第7个输出为int,DSA生成dropoutmask的长度。
约束说明
- 输入query、key、value的B:batchsize必须相等,取值范围1~256。
- 输入query的N和key/value的N必须等长。
- 输入query、key、value、pse的数据类型必须一致。
- 输入query、key、value的input_layout必须一致。
- 输入key/value的shape必须一致。
- 输入query、key、value的S:sequence length必须等长,取值范围1~8K,且sequence length长度必须是256的倍数。
- 输入query、key、value的D:head dim,N、D仅支持如下组合:4 80;8 80;16 80;32 80;5 128;8 128;12 128。
- pre_tockens和next_tockens的取值不能小于0。
- sparseMode为2、3、4时,必须输入对应正确的attenMask。
- keep_prob的取值范围为(0, 1] 。
- 不支持带无效行(整行都是1)的atten_mask。
- sparse_mode配置为1、2、3时,用户配置的pre_tockens、next_tockens不会生效。
- sparse_mode配置为0、4时,须保证atten_mask与pre_tockens、next_tockens的范围一致。
- 支持SDXL的特定shape:在N=5,D=64时,query_len与key_len/value_len不等长,且query_len 64对齐且<=4k,key_len/value_len=512。
- 不支持确定性计算。
支持的PyTorch版本
- PyTorch 2.1
- PyTorch 2.0
- PyTorch 1.11.0
支持的型号
Atlas A2训练系列产品
调用示例
import math
import unittest
import numpy as np
import torch
import torch_npu
from torch_npu.testing.testcase import TestCase, run_tests
from torch_npu.testing.common_utils import get_npu_device

DEVICE_NAME = torch_npu.npu.get_device_name(0)[:10]


class TestNPUFlashAttention(TestCase):
    def supported_op_exec(self, query, key, value):
        qk = torch.matmul(query, key.transpose(2, 3)).mul(0.08838)
        softmax_res = torch.nn.functional.softmax(qk, dim=-1)
        output = torch.matmul(softmax_res, value)
        output = output.transpose(1, 2)
        output = output.reshape(output.shape[0], output.shape[1], -1)
        return output

    def custom_op_exec(self, query, key, value):
        scale = 0.08838
        return torch_npu.npu_fusion_attention(
            query, key, value, head_num=32, input_layout="BSH", scale=scale)

    def trans_BNSD2BSH(self, tensor: torch.Tensor):
        tensor = torch.transpose(tensor, 1, 2)
        tensor = torch.reshape(tensor, (tensor.shape[0], tensor.shape[1], -1))
        return tensor

    def test_npu_flash_attention(self, device="npu"):
        query = torch.randn(1, 32, 128, 128, dtype=torch.float16)
        key = torch.randn(1, 32, 128, 128, dtype=torch.float16)
        value = torch.randn(1, 32, 128, 128, dtype=torch.float16)

        q_FA = self.trans_BNSD2BSH(query).npu()
        k_FA = self.trans_BNSD2BSH(key).npu()
        v_FA = self.trans_BNSD2BSH(value).npu()
        output = self.supported_op_exec(query.float(), key.float(), value.float())
        attention_score, softmax_max, softmax_sum, softmax_out, seed, offset, numels = self.custom_op_exec(q_FA, k_FA, v_FA)
        self.assertRtolEqual(output.half(), attention_score, prec=0.005, prec16=0.005)

if __name__ == "__main__":
    run_tests()